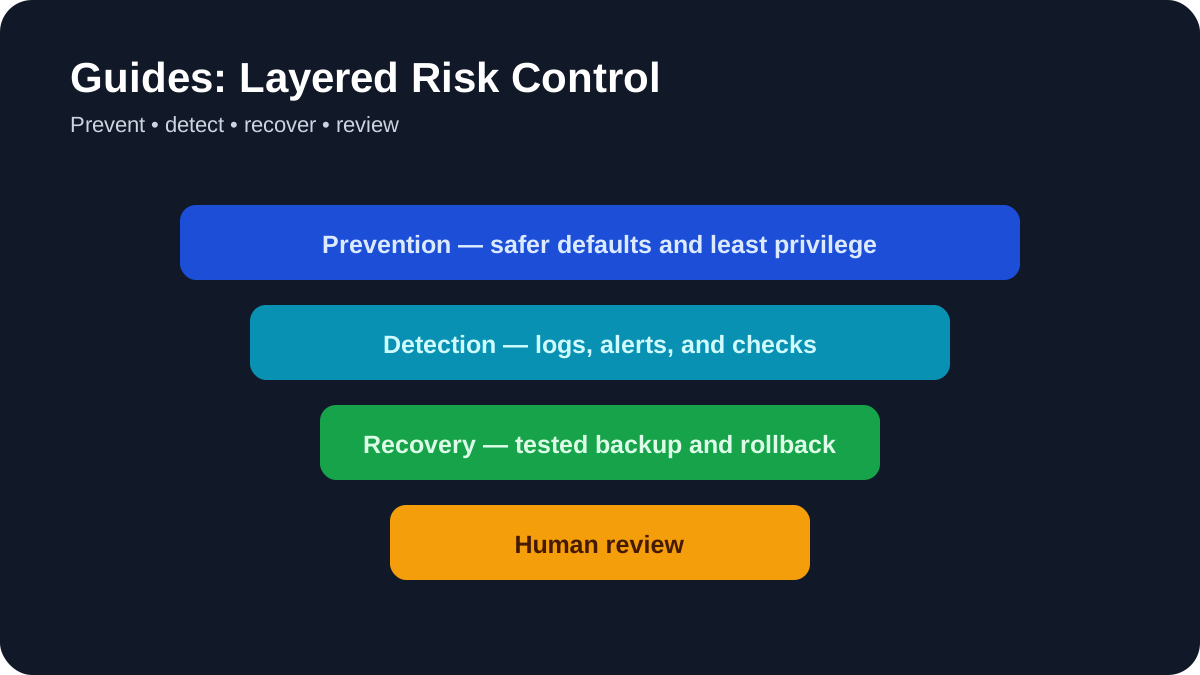
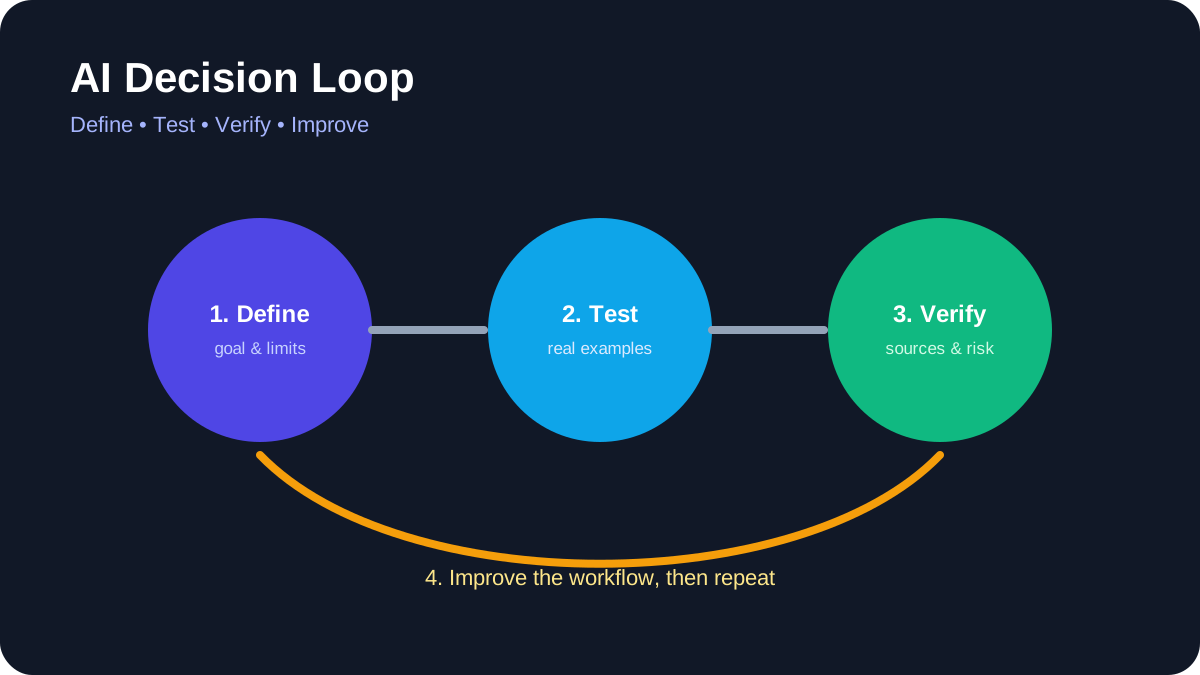
Layered Risk Control. Use prevention, detection, recovery, and human review together.
Moving an AI idea from a demonstration to a dependable system requires more than choosing a model. This implementation guide explains how to define the problem, create a baseline, build a limited prototype, evaluate failures, protect data, and introduce the system gradually.
Quick answer
Start with a documented user need and a non-AI baseline. Build the smallest reversible prototype, evaluate it with representative data, assign human accountability, and test security and failure handling before connecting production systems.
Best for: small teams planning an AI assistant, retrieval system, classifier, content workflow, or agent.
Phase 1: Define the decision and its consequences
Describe who will use the system, what information it receives, what it produces, and what happens if it is wrong. Separate low-impact assistance from decisions involving health, employment, finance, legal rights, safety, or access to essential services. High-consequence uses require qualified governance and domain expertise beyond a general tutorial.
Assign an owner before development begins. The owner is responsible for approving requirements, reviewing evidence, responding to incidents, and deciding when the system should be disabled.
Phase 2: Establish a baseline
Document how the work is completed today. Record quality criteria, turnaround time, common errors, operating cost, and user complaints where those measurements are legitimately available. An AI prototype should be compared with this baseline, not with an idealized promise.
Consider whether a search function, template, rule-based automation, or conventional software change can solve the problem more reliably. AI should be used because its capabilities match the task, not because it is fashionable.
Phase 3: Map data and permissions
List each data source, its owner, sensitivity, retention rule, and permitted use. Remove unnecessary personal information and secrets from development data. Use test accounts and synthetic examples where possible.
For integrations, grant access to the smallest required resource. Separate development and production credentials, store secrets outside source code, and define a revocation process. The NIST AI Risk Management Framework emphasizes mapping context and governing risk throughout the lifecycle rather than treating safety as a final checklist.
Phase 4: Build a narrow prototype
Limit the first version to one input path and one output. Keep model instructions, retrieval settings, prompts, schemas, and dependencies under version control. Record the model or service used and the date because hosted behavior can change.
If the system generates structured data, validate it against a schema. If it retrieves documents, show the source passages to the reviewer. If it can call tools, begin with read-only access and require approval before any consequential action.
Phase 5: Create an evaluation set
Build tests from realistic cases, including incomplete data, conflicting sources, unusual formatting, malicious instructions, and requests outside scope. Define success before running the system. Useful measures depend on the task and may include factual support, completeness, classification error, citation accuracy, refusal behavior, latency, cost, and human correction effort.
Do not rely only on an AI model to grade another AI model. Automated evaluation can help screen large sets, but important conclusions need human review and task-specific evidence.
Phase 6: Test retrieval and grounding
For retrieval-augmented generation, evaluate retrieval separately from generation. Confirm whether the system found the correct documents before judging the final answer. Test access control so users cannot retrieve material they are not authorized to view.
Require citations that point to accessible source material. A citation is not sufficient if the cited passage does not support the answer. Define what the system should do when no reliable source is available.
Phase 7: Threat-model the workflow
OWASP documents risks including prompt injection, sensitive information disclosure, supply-chain weaknesses, excessive agency, and improper output handling. Test whether untrusted documents or web pages can alter system instructions. Treat model output as untrusted input before passing it to code, databases, browsers, or external tools.
Set limits on actions, cost, runtime, and repeated calls. Log tool requests and human approvals. Never allow an agent to silently expand its own permissions.
Phase 8: Design human review
Human-in-the-loop must mean more than placing an approval button on the screen. Reviewers need the original input, relevant sources, uncertainty, changes made, and a practical way to correct or reject the result. Workload must be realistic; a reviewer cannot meaningfully inspect hundreds of high-risk outputs in seconds.
Document which decisions remain human responsibility. AILooma’s guide to using AI agents without losing control provides additional approval and audit-log patterns.
Phase 9: Prepare operations and rollback
Define monitoring, incident reporting, user feedback, model or dependency updates, backups, and rollback. Track changes to prompts, retrieval indexes, model versions, evaluation data, and permissions. Re-run important tests after each material change.
Create a kill switch that owners understand. Preserve a manual process for critical work until the new system has demonstrated reliable operation under normal conditions.
Phase 10: Release gradually
Begin with internal users, low-risk data, and limited scope. Review failures frequently, then expand only when evidence supports it. Tell users when they are interacting with AI and how to report a problem. Avoid presenting generated answers as authoritative when uncertainty remains.
Implementation readiness checklist
The user need and non-AI alternative are documented.
An accountable owner and escalation path exist.
Data sources, permissions, and retention are approved.
Evaluation includes normal, edge, and adversarial cases.
Sources and outputs can be inspected by reviewers.
External actions require appropriate approval.
Monitoring, versioning, rollback, and incident response are tested.
Users receive clear disclosure and a feedback path.
Final takeaway
A responsible AI implementation is a managed system, not a clever prompt. The strongest teams make scope, evidence, ownership, permissions, and rollback visible from the beginning. That discipline makes it easier to improve the system and safer to stop it when the evidence changes.
Practical example: moving an AI prototype toward production
Imagine an internal assistant that summarizes support tickets. Before launch, write a one-page release plan that names the users, allowed data, success measures, owner, escalation path, and rollback trigger.
Start with a small pilot group and synthetic or redacted examples.
Measure task success, citation quality, latency, cost, and the rate of human corrections.
Log prompts and outputs with access controls and a retention period.
Require a human approval step for external messages or consequential decisions.
Define how to pause the system, revert a prompt or model version, and notify users.
This turns “the demo works†into an accountable operating process. A production decision should be based on evidence from the intended workflow, not a single impressive sample.
Practical verification and limits
Define success and failure thresholds, assign an owner, test data quality and security, keep human approval for consequential actions, and document rollback conditions.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. Recommendations are based on documented behavior and reproducible checks. Tools, models, and policies can change; verify current details before acting.
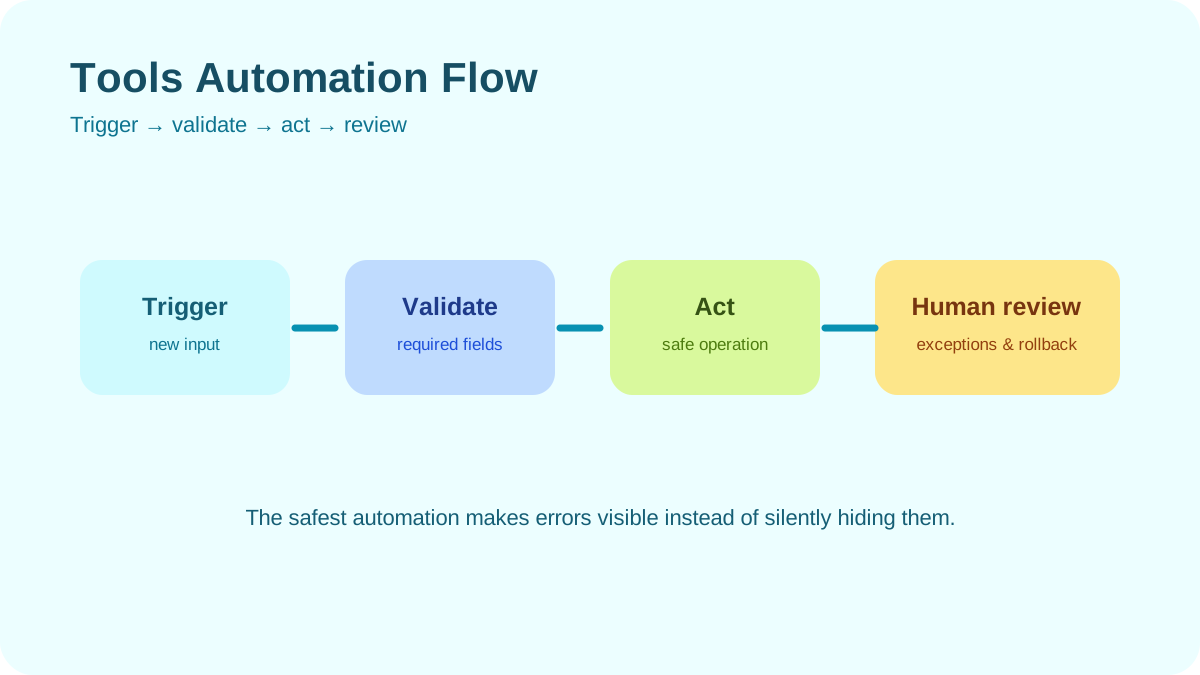
Tools Automation Flow. Move from trigger to validation, safe action, and human review.
AI tools change quickly, but the process for learning them can remain stable. This guide provides a practical workflow for evaluating a new AI tool, learning its core features, testing it with realistic examples, and deciding whether it belongs in your work.
Quick answer
Begin with one task, use non-sensitive sample data, read the official documentation, and create a small test set. Compare the AI output with a trusted source, document failures, and check export, privacy, pricing, and permission controls before adopting the tool.
Best for: professionals comparing writing, research, design, meeting, coding, or automation tools.
Why task-first evaluation works
A feature list does not show whether a product fits your workflow. Start by writing down the job you need completed, the acceptable input, the expected output, and the person responsible for checking it. This prevents a polished demonstration from becoming a substitute for evidence.
For example, “help with research” is too broad. “Extract the main claims from five public documents and provide a link to the source of each claim” is testable. The clearer task also exposes whether the tool supports citations, structured output, and correction.
Step 1: Check the official product information
Use the vendor’s documentation to confirm supported platforms, account requirements, current plan limits, data controls, and export options. Do not rely on an old tutorial for pricing or interface details. Save the documentation links you used and record the date of the evaluation.
For workplace use, review whether administrators can control sharing, retention, integrations, and access. A tool that is acceptable for public marketing copy may be inappropriate for customer records, contracts, source code, or internal strategy.
Step 2: Define a representative test set
Create several examples from the type of work you actually perform, but remove personal or confidential information. Include normal cases, incomplete inputs, contradictory information, and a request the system should refuse or mark as uncertain.
Write the expected result before running the test. Without a reference point, users tend to reward fluent wording even when the output is incomplete or wrong.
Step 3: Learn the smallest useful workflow
Ignore advanced integrations at first. Learn how to create a task, provide context, revise an instruction, inspect sources, export the result, and delete test data. Complete the same workflow several times before adding templates or automation.
If the tool supports reusable instructions, keep them short and versioned. Explain the intended audience, required format, evidence rules, and prohibited actions. Test changes against the same examples so you can identify regressions.
Step 4: Evaluate accuracy and usefulness separately
An output can be readable but inaccurate, or accurate but unusable. Score factual support, completeness, format compliance, clarity, and the amount of human correction required. For research tasks, open every important source. For calculations, reproduce the result independently.
Use AILooma’s practical framework for evaluating AI answers when the output may inform a decision. Keep examples of failures; they are essential for defining where human review is required.
Step 5: Inspect privacy and permissions
Before uploading real data, confirm what the service stores, who can access shared workspaces, whether inputs may be used to improve models, and how deletion works. Settings differ between products and plans, so use the current official privacy and administration pages.
Give integrations the minimum permission required. Avoid granting access to an entire mailbox, drive, repository, or customer database when a limited folder or test account will work. AILooma’s guide to protecting sensitive data when using AI tools covers this decision in more detail.
Step 6: Test interoperability and recovery
Export a result in a format you can use without the product. Check whether links, formatting, comments, and structured fields survive. If the tool creates automations, test duplicate events, invalid inputs, rate limits, and service outages.
Document how to disable the integration and revoke credentials. A tool is easier to adopt responsibly when leaving it is also straightforward.
Step 7: Measure a real baseline
Complete the task manually and record the time, corrections, and final quality. Then repeat with the AI-assisted workflow. Do not publish a percentage improvement from a single trial. Use enough repetitions to understand normal variation and include review time in the comparison.
Examples of task-specific learning
Writing and editing
Test whether the tool can transform a supplied draft while preserving facts, citations, tone, and required terminology. Compare edits line by line and retain the human-approved original.
Research
Require links to primary sources and reject unsupported claims. A research assistant should help locate and organize evidence, not become the evidence.
Design
Check licensing, provenance, accessibility, editable exports, and consistency across variations. Canva documents its AI tools and current usage limitations in its official help center.
Workspace assistance
For products such as Notion AI, test permissions with a small workspace and read the current help documentation. Confirm which connected sources the assistant can search and which account plan controls availability.
Automation
Keep a human approval step before external messages, publication, purchases, deletion, or permission changes. Log the input, output, tool call, failure, and approval.
Adoption checklist
The task and owner are defined.
Official documentation and current plan terms were reviewed.
Tests use safe, representative data.
Important claims are independently verifiable.
Permissions follow least privilege.
Check whether the tool supports export and deletion, then verify both controls using non-sensitive sample data before relying on them.
Failure handling and rollback are documented.
The benefit remains after review time and subscription cost are included.
Final takeaway
Learning an AI tool is not about mastering every button. It is about understanding one workflow well enough to predict its value, detect its failures, and maintain control. A disciplined evaluation makes product changes less disruptive because your method survives when the interface does not.
Practical example: a one-hour evaluation of a new AI tool
Before adopting an unfamiliar AI service for work, use a small test pack rather than a single impressive prompt. Include one normal request, one ambiguous request, one request containing a deliberate factual trap, and one request that contains sensitive information replaced with safe placeholders.
Record the tool version, plan, usage limits, and data-retention description.
Run the same test pack twice to see whether results are stable.
Check citations, export quality, error handling, and whether the tool clearly signals uncertainty.
Inspect permissions and revoke access that is not needed for the test.
Decide whether the tool is suitable for production, limited experiments, or neither.
Save the test notes and a redacted output sample. A repeatable evaluation record helps a team explain why it adopted a tool and gives it a baseline for checking future updates.
Practical verification and limits
Use a representative test set, score accuracy and editing effort, review retention and permissions, and run a limited pilot before connecting sensitive work.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. Recommendations are based on documented behavior and reproducible checks. Tools, models, and policies can change; verify current details before acting.
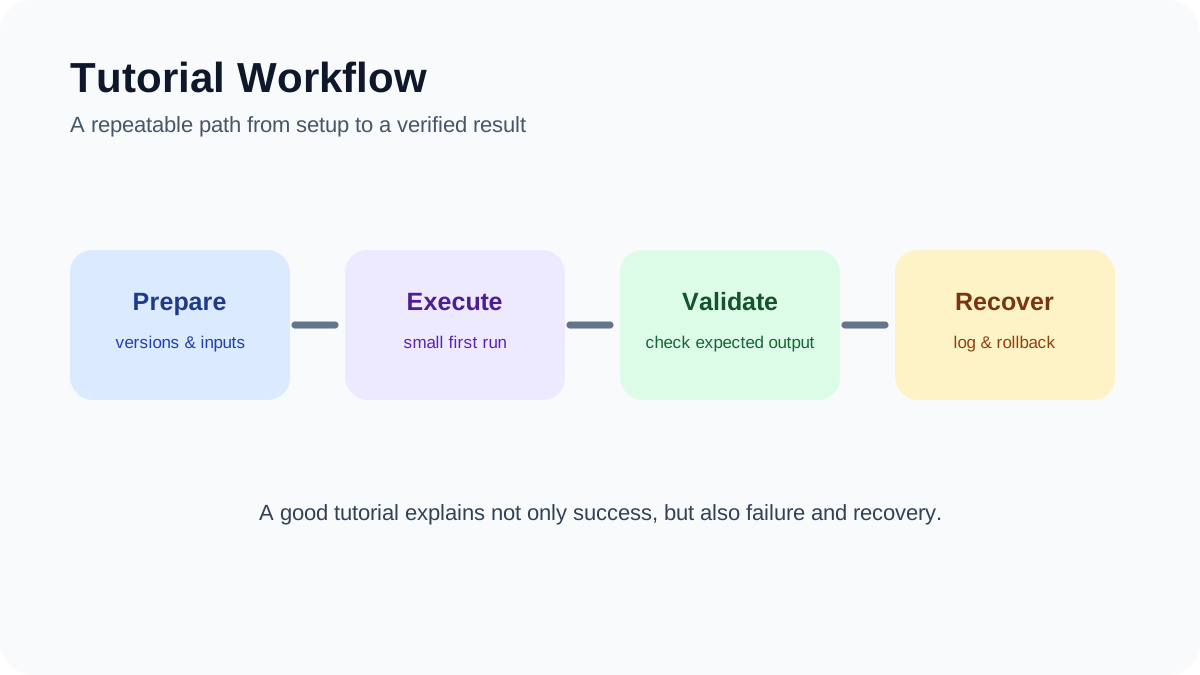
Tutorial Workflow. A repeatable path from preparation and execution to validation and recovery.
Learning artificial intelligence from scratch is easier when you begin with one useful task instead of trying to understand every model, tool, and technical term at once. This project-based tutorial shows beginners how to choose a safe first use case, test an AI output, document mistakes, and decide whether coding is necessary.
Quick answer
Start with a low-risk task such as summarizing your own notes, classifying non-sensitive text, or comparing two drafts. Use sample data, keep the original source beside the output, and record what the AI gets right and wrong. Only add automation or code after the manual workflow is reliable.
Best for: students, creators, office workers, and career changers with little or no AI experience.
What you will learn
By the end of this tutorial, you will understand the difference between using an AI application and building an AI system. You will also have a small completed project, a repeatable evaluation checklist, and a clearer idea of which learning path to follow next.
Step 1: Choose one narrow problem
A useful beginner project has a clear input, a visible output, and a simple way to check the result. Good examples include turning meeting notes into an action list, grouping customer questions by topic, explaining unfamiliar terminology, or drafting alternative headlines. Avoid medical, legal, financial, employment, or security decisions while you are still learning.
Write the task in one sentence: “Given this input, produce this output for this audience.” That sentence becomes the boundary of the experiment. If the task requires access to private workplace material, replace it with fictional or anonymized examples.
Step 2: Build a small test set
Collect several representative examples rather than judging the tool from one impressive response. Include an easy example, an ambiguous example, and an example that should cause the model to say it lacks enough information. Keep the expected result or original source available for comparison.
A spreadsheet is enough for tracking. Use columns for the input, prompt, output, factual errors, missing details, useful details, and final decision. This creates evidence you can revisit when the tool, prompt, or model changes.
Step 3: Write a prompt that can be checked
State the task, provide the necessary context, define the output format, and tell the model how to handle uncertainty. For example: “Summarize these notes into decisions, owners, and open questions. Do not invent missing owners. Mark uncertain items as unconfirmed.”
A longer prompt is not automatically better. The goal is a clear instruction whose output can be compared with the source. Never treat a confident tone as proof that an answer is correct.
Step 4: Review the output manually
Check names, dates, numbers, quotations, links, and conclusions against the original material. Look for omitted context as well as fabricated details. If the answer cites a source, open that source and confirm that it actually supports the claim.
AILooma’s guide to fact-checking AI-generated answers provides a deeper verification workflow. The central rule is simple: an AI output is a draft or hypothesis until reliable evidence confirms it.
Step 5: Change one variable at a time
If the result is weak, revise one part of the prompt and run the same test set again. Changing the model, prompt, data, and settings simultaneously makes it difficult to understand what improved or degraded the result.
Keep a short version history. Record the prompt, date, tool, relevant settings, and a sentence explaining why you changed it. This habit is more useful than collecting large libraries of untested prompts.
Step 6: Decide whether you need code
No-code tools are suitable for learning concepts and testing a workflow. Coding becomes useful when you need repeatability, structured data, version control, custom validation, or integration with another system. Python is common in AI education, but it is not a prerequisite for understanding responsible use.
If you want hands-on coding practice, official resources such as Kaggle Learn, TensorFlow Tutorials, and Hugging Face Learn provide guided exercises. Follow the current setup instructions on each official site because interfaces and dependencies change.
Step 7: Add automation only after testing
Automation increases both convenience and risk. Before connecting email, cloud storage, calendars, or publishing systems, test with non-sensitive data and require human approval for sending, deleting, purchasing, publishing, or changing permissions.
Define what happens when an input is missing, an API is unavailable, or the output fails validation. A workflow is not ready merely because it succeeds once.
How to choose your next learning resource
Choose a resource based on the project you want to complete. Non-technical learners may start with Google AI Essentials or another introductory course that focuses on everyday tasks. Learners who want to work with open models can use Hugging Face’s current courses. People interested in machine learning fundamentals can begin with Kaggle or TensorFlow notebooks.
Before paying for a course, inspect its syllabus, prerequisites, update history, refund terms, and sample lessons. Product-specific courses age quickly, so current official documentation should remain part of your learning process.
Beginner evaluation checklist
Can you describe the task and expected output in one sentence?
Are you using public, fictional, or properly authorized data?
Do you have examples that include both normal and difficult cases?
Can every factual statement be checked against a reliable source?
Have you recorded failures as well as successful outputs?
Can you stop or reverse the workflow if something goes wrong?
Do you know which part still requires human judgment?
Common mistakes
Tutorial hopping creates familiarity without practical skill. Tool overload makes comparison difficult. Copying prompts without understanding the input and evaluation method produces fragile results. The most productive approach is to finish one small project, document it honestly, and then increase complexity.
Do not claim that a tool saved time or improved quality unless you measured the same task before and after using it. Do not upload confidential material merely because a tutorial does so. Always check the tool’s current data controls and your organization’s policies.
Final takeaway
Your first AI project does not need to be impressive. It needs to be understandable, testable, and safe. A small workflow with documented limitations teaches more than a large demonstration you cannot explain. Once you can evaluate the result consistently, you are ready to explore automation, APIs, local models, or more technical coursework.
A manageable learning plan can produce one small, inspectable project each week. Week one focuses on prompts and data hygiene; week two compares outputs on a fixed test set; week three adds a simple script or notebook; week four documents limitations and presents the result.
Choose one recurring problem and define what a successful answer looks like.
Collect a small, lawful, and representative sample while removing personal information.
Keep prompts, model versions, dates, and evaluation notes in a simple log.
Review failures manually and adjust one variable at a time.
Write a short README explaining how another learner can reproduce the exercise.
The project is valuable even when the model performs imperfectly. The learning comes from defining a task, measuring it, understanding failure modes, and communicating what should—and should not—be trusted.
Practical verification and limits
Start with a small project using non-sensitive data, define a measurable output, compare AI results with a trusted reference, and record what failed before adding automation.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. Recommendations are based on documented behavior and reproducible checks. Tools, models, and policies can change; verify current details before acting.
Tutorial Workflow. A repeatable path from preparation and execution to validation and recovery.
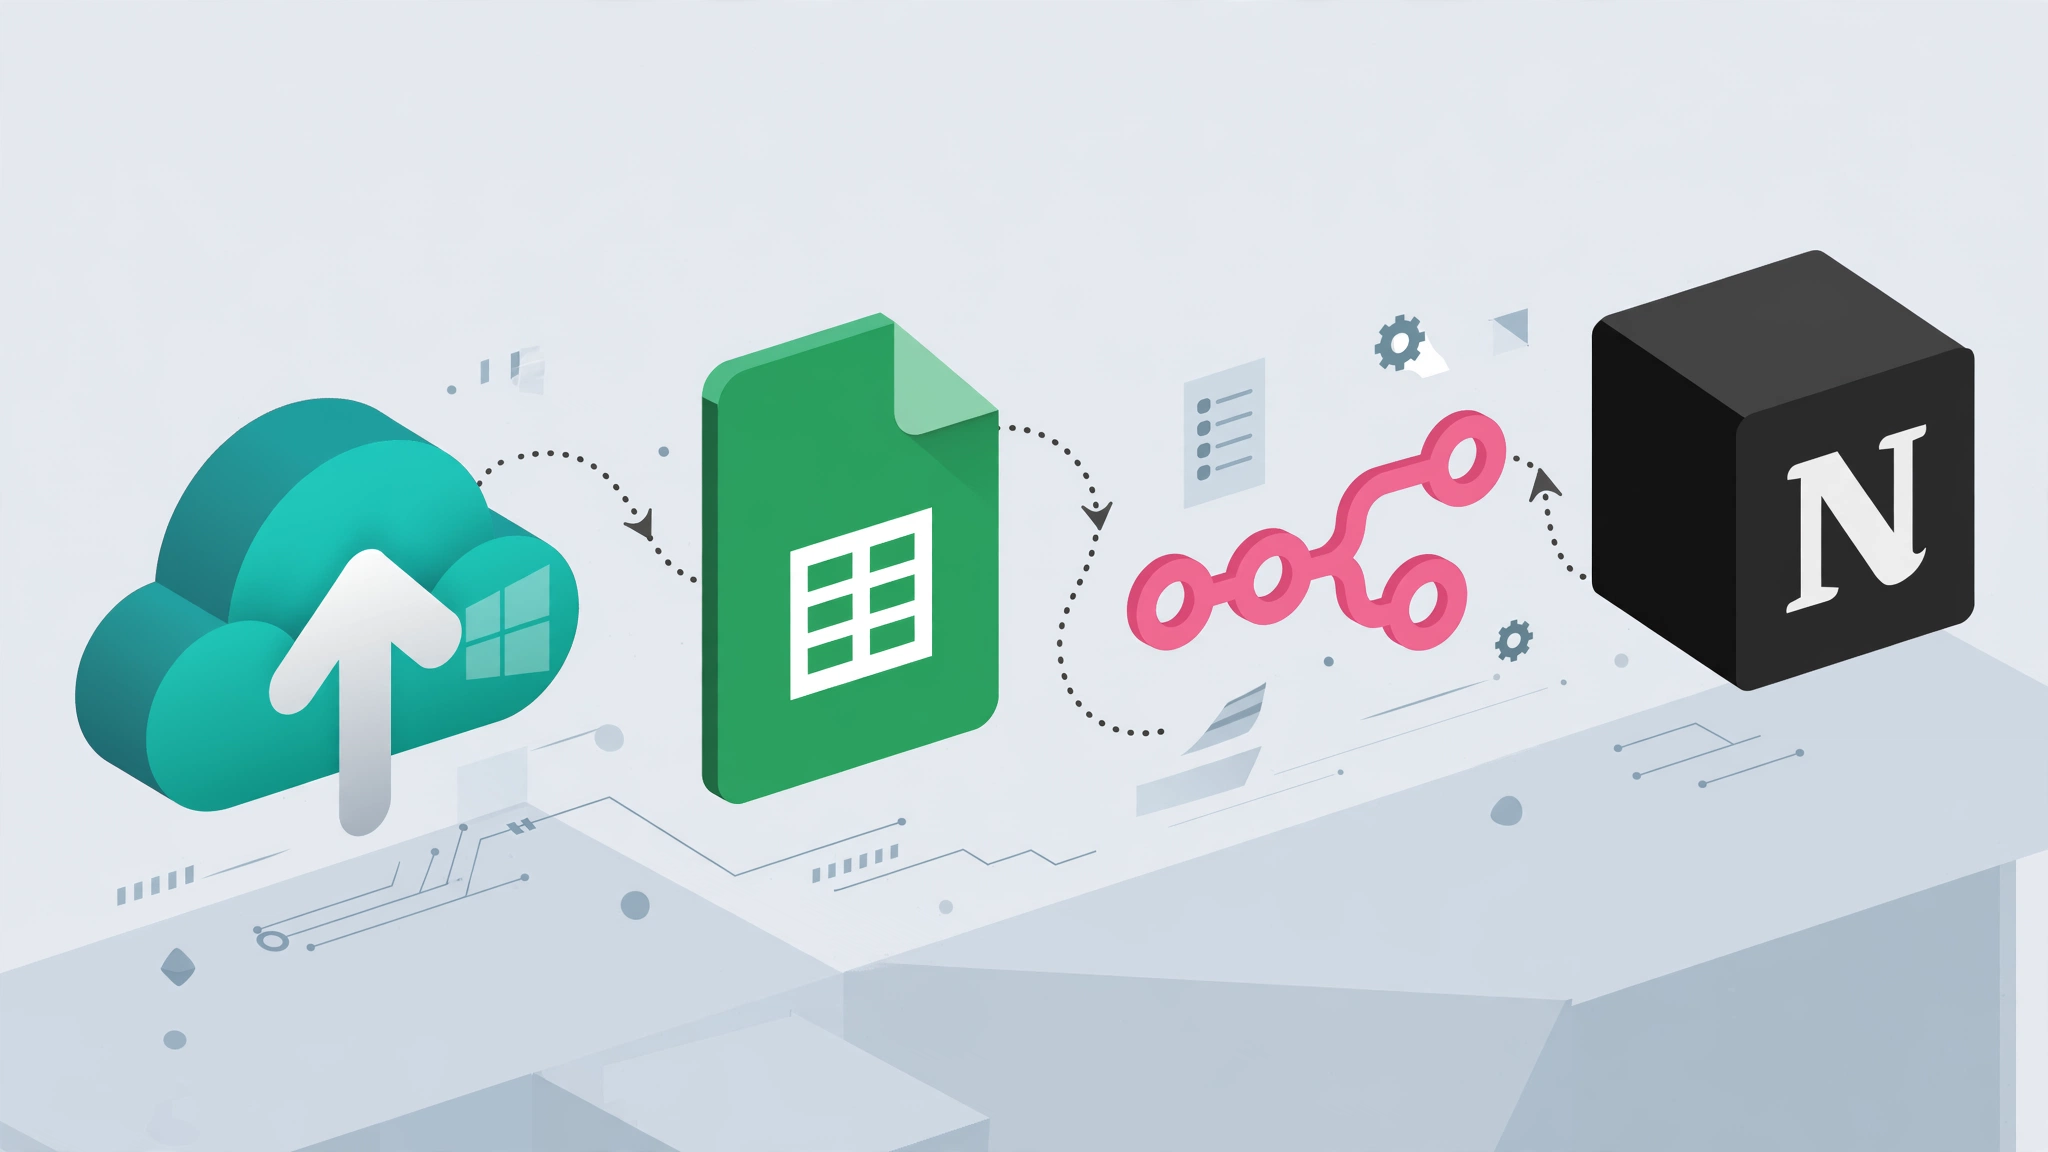
Notion, Windows, n8n, and Google Sheets can work together to create a useful automation stack—but they should not all be treated as the same thing.
Notion can hold structured project data. n8n can orchestrate workflows. Windows can store independent file backups. Google Sheets can provide a simple human-readable activity log.
The important part is designing clear boundaries between those roles.
This guide shows how to build a practical Notion backup and activity-log workflow with n8n on Windows without confusing synchronization, export, logging, and backup.
What This Workflow Actually Does
The architecture looks like this:
Notion
   ↓
n8n detects or polls relevant records
   ↓
Record metadata / workflow event
   ↓
Optional export or local artifact process
   ↓
Windows backup destination
   ↓
Google Sheets activity log
Each layer has a different responsibility.
Notion: stores the working information.
n8n: coordinates actions between systems.
Windows: stores local or network backup copies where applicable.
Google Sheets: records activity and backup status.
Important: A Sync Is Not Automatically a Backup
If a Notion record is copied into another live system and changes in both places, that is synchronization.
A backup should give you an independent copy that can be recovered after accidental deletion, corruption, account loss, or another failure.
For example:
Notion → Google Sheets
is primarily data synchronization or logging.
By contrast:
Exported Files → External Drive / NAS
is closer to a traditional backup.
What Windows File History Can Protect
Windows File History can automatically protect supported personal files by saving copies to an external drive or network location. Microsoft documents it as a file-versioning and recovery feature for personal files. :contentReference[oaicite:1]{index=1}
That makes it useful for local files generated by your workflow.
However, File History does not directly back up a Notion workspace simply because the Notion desktop application is installed.
You first need a real local file or export that Windows can protect.
The Critical Notion Limitation
Notion’s API is useful for reading and updating structured workspace content that an integration can access.
But you should not design a workflow around the assumption that the API provides a simple one-command equivalent of:
Export this Notion page exactly as Markdown/PDF
for every workspace object.
If you need archival copies, distinguish between:
data retrieved through the Notion API;
workspace or page exports provided through Notion’s export functionality;
third-party exporters.
Third-party exporters introduce another dependency and should not be presented as native Notion or n8n functionality.
A Safer First Version
Instead of beginning with a complicated page-export system, start by automating a structured Notion database.
For example, imagine a Notion database containing:
Project ID;
Project Name;
Status;
Owner;
Last Edited;
Backup Required;
Local Folder.
n8n can periodically inspect those records and decide whether another action is required.
Step 1: Decide What Notion Is Responsible For
Do not make Notion responsible for everything.
For example:
Information
System of Record
Project status
Notion
Actual project files
Windows / file storage
Backup copies
External drive / NAS / backup storage
Automation status
Google Sheets or local log
This avoids turning one application into an unreliable source of truth for everything.
Step 2: Create a Stable Project ID
Every monitored Notion record should have a stable identifier.
For example:
PROJECT-001
PROJECT-002
PROJECT-003
Do not rely only on titles such as:
Website Redesign
because titles can change or be duplicated.
Step 3: Connect Notion to n8n
Create a Notion integration and grant it access only to the database or pages the workflow actually needs.
Apply least privilege.
If the workflow only reads project status, it should not automatically receive broad write access to unrelated workspace content.
Then configure the corresponding Notion credential in n8n using the current authentication options supported by your n8n version.
Step 4: Detect Relevant Notion Changes
The simplest architecture is scheduled polling.
Schedule Trigger
      ↓
Read Notion Records
      ↓
Filter Recently Changed Records
A schedule is often easier to understand and debug than event-driven infrastructure.
Store a checkpoint such as the last successful synchronization timestamp so the workflow can identify records that changed since the previous successful run.
Do Not Use “Now Minus Five Minutes” as Your Only State
Suppose the computer is turned off for two hours.
If the workflow only asks:
Give me records changed in the last five minutes
then changes made during the outage may be missed.
A better pattern is:
Last Successful Checkpoint
        ↓
Fetch Changes After Checkpoint
        ↓
Process Successfully
        ↓
Save New Checkpoint
Step 5: Separate Notion Data From Local Files
A Notion project may refer to local files such as:
C:\Projects\Client-A
The workflow should treat that path as a reference to another data source.
Notion itself does not make that folder backed up.
Step 6: Run the Backup Independently
For local Windows folders, the actual backup operation can use:
File History;
Robocopy;
dedicated backup software;
NAS backup software;
another approved backup system.
If you use Robocopy, keep destructive options out of the beginner workflow.
Timestamp
Project ID
Event
Source
Destination
Status
Verification
Duration
Error
Examples of events:
Notion Record Changed;
Backup Started;
Backup Completed;
Verification Passed;
Verification Failed;
Logging Failed.
Step 10: Keep Backup Status and Logging Status Separate
This distinction is essential.
Backup: SUCCESS
Google Sheets Log: FAILED
means your backup may still be safe.
Conversely:
Backup: FAILED
Google Sheets Log: SUCCESS
means the monitoring system worked but the actual backup did not.
Do not collapse those two states into one generic Status field.
Step 11: Keep a Local Queue
If Google Sheets or the network is unavailable, the workflow should not lose the event.
A practical architecture is:
Backup Result
    ↓
Local JSON / SQLite Queue
    ↓
Can Google Sheets Be Reached?
  ↙                 ↘
No                  Yes
↓                    ↓
Keep Event        Send Event
                     ↓
                 Mark Delivered
This makes remote logging eventually consistent without making it critical to the backup itself.
Step 12: Verify the Backup
A successful copy command does not necessarily mean recovery will work.
Possible verification methods include:
checking that the destination file exists;
comparing source and destination file sizes;
comparing hashes for selected files;
periodically restoring a test file.
A recovery test is usually more meaningful than simply having hundreds of “Success” rows in Google Sheets.
Step 13: Let Windows File History Protect Local Exports
If your workflow creates local Markdown, CSV, JSON, or other export artifacts, those files can become candidates for File History.
Microsoft states that File History can save versions of personal files to an external drive or network location and later restore earlier versions. :contentReference[oaicite:2]{index=2}
This is different from assuming File History directly understands Notion’s cloud data model.
Step 14: Avoid Backing Up the Notion Desktop Cache as Your Primary Strategy
A desktop application’s local cache should not automatically be treated as a documented backup format.
Internal cache structures may change between application versions and may not provide a clean recovery path.
If recoverability matters, use an intentional export or API-based archive format rather than relying on undocumented cache files.
Step 15: Be Careful With Execute-Command Workflows
If n8n runs local commands or PowerShell scripts, those commands execute in the environment where n8n itself is running.
This matters especially with Docker or remote servers.
For example:
n8n running on remote Linux server
        ↓
Execute local command
        ↓
Command runs on Linux server
It does not magically execute on your Windows desktop.
If the workflow must manipulate Windows files, n8n or an authorized helper process needs a deliberate way to reach the Windows environment.
Step 16: Local n8n Is Not Automatically Required
The original workflow treated local n8n as mandatory.
A better distinction is:
Cloud n8n Can Handle
Notion API requests;
Google Sheets logging;
other internet-accessible APIs.
A Local Component Is Needed When
the workflow must access Windows-only local paths;
it must run local PowerShell;
it must interact with a private LAN resource unavailable externally.
You could therefore split the architecture between cloud orchestration and a local backup process if that fits the environment.
Step 17: Build Small Sub-Workflows
A modular architecture can be easier to maintain.
Workflow A: Notion Activity
Schedule
  ↓
Read Changed Records
  ↓
Normalize
  ↓
Queue Event
Workflow B: Windows Backup
Schedule / Local Trigger
  ↓
Backup Folder
  ↓
Verify
  ↓
Queue Result
Workflow C: Google Sheets Logger
Read Pending Events
  ↓
Append Rows
  ↓
Mark Delivered
Workflow D: Error Notification
Failure Event
  ↓
Classify Error
  ↓
Notify if Action Required
This is easier to troubleshoot than one enormous workflow containing every possible responsibility.
Step 18: Retry Only the Right Failures
Some failures are transient.
Examples:
network timeout;
temporary API unavailability;
rate limiting.
Retries may help.
Other failures are not transient:
invalid credentials;
permission denied;
invalid destination path;
disk full;
invalid workflow configuration.
Blindly retrying those problems can create noise without fixing anything.
Step 19: Keep Sensitive Data Out of the Log
Google Sheets should contain only the metadata required for monitoring.
Avoid logging:
Notion API tokens;
Google credentials;
document contents;
private customer data unless required;
full stack traces containing secrets;
sensitive local paths when a project ID would be enough.
Step 20: Use Least-Privilege Credentials
Notion integration permissions should match the workflow’s purpose.
Google credentials should only have access to the spreadsheet or resources they require.
n8n users should only have the ability to edit production workflows when their role requires it.
Do not store tokens directly in workflow code.
Step 21: Service Account vs OAuth for Google Sheets
Both can be appropriate.
Service Account
Useful for controlled unattended automation when the spreadsheet is shared with the service identity.
User OAuth
Useful when the workflow should operate specifically as an authenticated user.
Do not grant a service account broad Google Cloud project roles simply because it needs to update one Sheet.
Spreadsheet access and Google Cloud IAM are separate concerns.
Step 22: Avoid Arbitrary Key Rotation Rules
A blanket rule such as:
Rotate every service account key every 90 days
should not be presented as universally required.
Credential strategy should follow the organization’s security requirements and the authentication architecture being used.
Where possible, minimize long-lived credential material instead of creating unnecessary manual key-rotation work.
Step 23: Do Not Run CHKDSK /f as Routine Maintenance Without Reason
Commands that can modify a filesystem should not be included in a generic quarterly automation checklist.
Disk health monitoring and filesystem repair are different tasks.
Use diagnostic or repair tools when there is a real reason and after understanding their effects.
Step 24: Compression Is Optional
You can compress export artifacts before archiving them, but maximum compression is not automatically better.
Consider:
archive size;
CPU time;
recovery simplicity;
whether the file types compress well;
whether individual-file recovery is important.
Do not introduce 7-Zip, multi-volume archives, or another archival layer unless it solves a real problem.
Step 25: Sync Is Still Not Backup
Tools such as Syncthing can replicate files between devices.
That can improve redundancy, but synchronization can also propagate deletion or corruption depending on configuration.
If Syncthing or another sync tool is added, keep at least one independent recovery copy or versioned backup.
Step 26: Test the Entire Recovery Path
Testing should include more than API connectivity.
Useful scenarios:
Notion API temporarily unavailable;
Google Sheets unavailable;
backup drive disconnected;
local disk full;
duplicate workflow execution;
invalid source path;
computer offline during a scheduled run;
restoring an actual file from backup.
Step 27: Make Missed Runs Recoverable
For scheduled Windows jobs, consider configuring them to run after a missed start where appropriate.
But workflow logic should also store checkpoints.
That way:
PC off for 6 hours
     ↓
PC starts
     ↓
Workflow resumes
     ↓
Processes events since last confirmed checkpoint
instead of looking only at events from the last few minutes.
A Practical Final Architecture
                    ┌───────────────┐
                    │    Notion     │
                    └──────┬────────┘
                           │
                    Metadata / Changes
                           │
                           ▼
                    ┌───────────────┐
                    │      n8n      │
                    └──────┬────────┘
                           │
               Monitoring / Coordination
                           │
              ┌────────────┴────────────┐
              ▼                         ▼
      Windows Backup Process      Activity Queue
              │                         │
              ▼                         ▼
       External / NAS Copy       Google Sheets
              │
              ▼
         Verification
              │
              ▼
          Restore Test
What This Stack Is Good For
small-team project monitoring;
Notion database activity tracking;
linking project metadata to local backup processes;
human-readable backup status;
simple automation experiments;
personal or small-business workflows.
What This Stack Is Not
It should not automatically be presented as:
a compliance platform;
a legal record-management system;
a complete disaster-recovery architecture;
a replacement for enterprise backup software;
a guaranteed immutable audit trail;
a research data management system by itself.
Security Checklist
Limit Notion integration access.
Limit Google Sheet sharing.
Keep secrets out of workflow code.
Protect n8n credentials.
Minimize execution-log retention where sensitive data is involved.
Keep backup storage independent from Google Sheets.
Do not expose local n8n unnecessarily.
Test restore procedures periodically.
How This Guide Was Prepared
This guide separates four concepts that are frequently mixed together in automation tutorials: Notion data access, workflow orchestration, file backup, and activity logging.
Windows File History is treated as a Windows file-recovery mechanism for supported local files rather than as a direct Notion workspace backup. Microsoft currently documents File History as saving copies of personal files to an external drive or network location for later restoration. :contentReference[oaicite:3]{index=3}
The Notion, n8n, Google Sheets, and Windows components in this guide are architectural building blocks. Node names, APIs, authentication options, export behavior, and platform features can change over time.
For that reason, implementation-specific details should be checked against current official documentation before deployment.
The examples are workflow patterns, not claims that specific legal firms, research labs, enterprises, or other organizations currently use this exact architecture.
Frequently Asked Questions
Can n8n automatically back up my entire Notion workspace?
Not automatically in the same way that backup software copies a filesystem.
n8n can interact with Notion’s API and orchestrate export or archival processes, but the exact recoverable artifact depends on how you design the archive and what Notion exposes through its supported interfaces.
Can Windows File History back up Notion?
File History can protect supported local files.
If you intentionally create Notion export files in a folder that File History protects, those exported files can become part of the Windows backup process. :contentReference[oaicite:4]{index=4}
That is different from File History directly backing up the Notion cloud workspace.
Do I need WSL2?
No.
WSL2 may be useful for a Linux-oriented n8n environment, but it is not inherently required for a Windows backup-and-logging architecture.
Do I need PowerShell 7?
Not universally.
Use a supported PowerShell environment appropriate to the scripts and modules you actually need rather than treating one specific version as mandatory.
Can I use n8n Cloud?
Yes for cloud-accessible tasks such as Notion and Google Sheets automation.
But a cloud-hosted workflow cannot directly manipulate arbitrary files on your private Windows machine unless you deliberately provide a secure integration path.
Should Google Sheets store my backup files?
No.
Use Sheets for metadata and monitoring.
The recoverable files should live on a proper backup destination.
Is Syncthing a backup?
It is primarily a synchronization tool.
Depending on configuration, it can contribute to data redundancy, but it should not automatically replace independent versioned backup copies.
Is this architecture automatically GDPR, HIPAA, or SOC 2 compliant?
No.
Compliance depends on the complete technical and organizational environment, data involved, permissions, retention, agreements, procedures, and applicable jurisdiction.
Final Takeaway
The strongest version of this workflow is not an “all-in-one automatic Notion backup machine.”
It is a set of clearly separated systems:
Notion manages working project data.
n8n coordinates events and integrations.
Windows or another backup system creates independent file copies.
Google Sheets provides a readable activity and monitoring log.
Keep those responsibilities separate and the workflow becomes much easier to reason about, troubleshoot, and recover.
Start with one Notion database, one local project folder, one backup destination, and one Google Sheets log.
Then test the most important thing:
Can you actually restore the file when something goes wrong?
Separate collection from approval, keep sensitive backup details out of shared sheets, record execution evidence, and test rollback before enabling scheduled runs.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. This guidance favors documented, reversible checks. Product APIs, permissions, and policies can change; verify current details before acting.
Tutorial Workflow. A repeatable path from preparation and execution to validation and recovery.
Google Sheets and Notion are both useful for organizing structured information, but they often end up containing the same data in different places.
A marketing team may track campaign metrics in Google Sheets while keeping project documentation in Notion. A support team may collect requests in a spreadsheet but manage follow-up work in a Notion database.
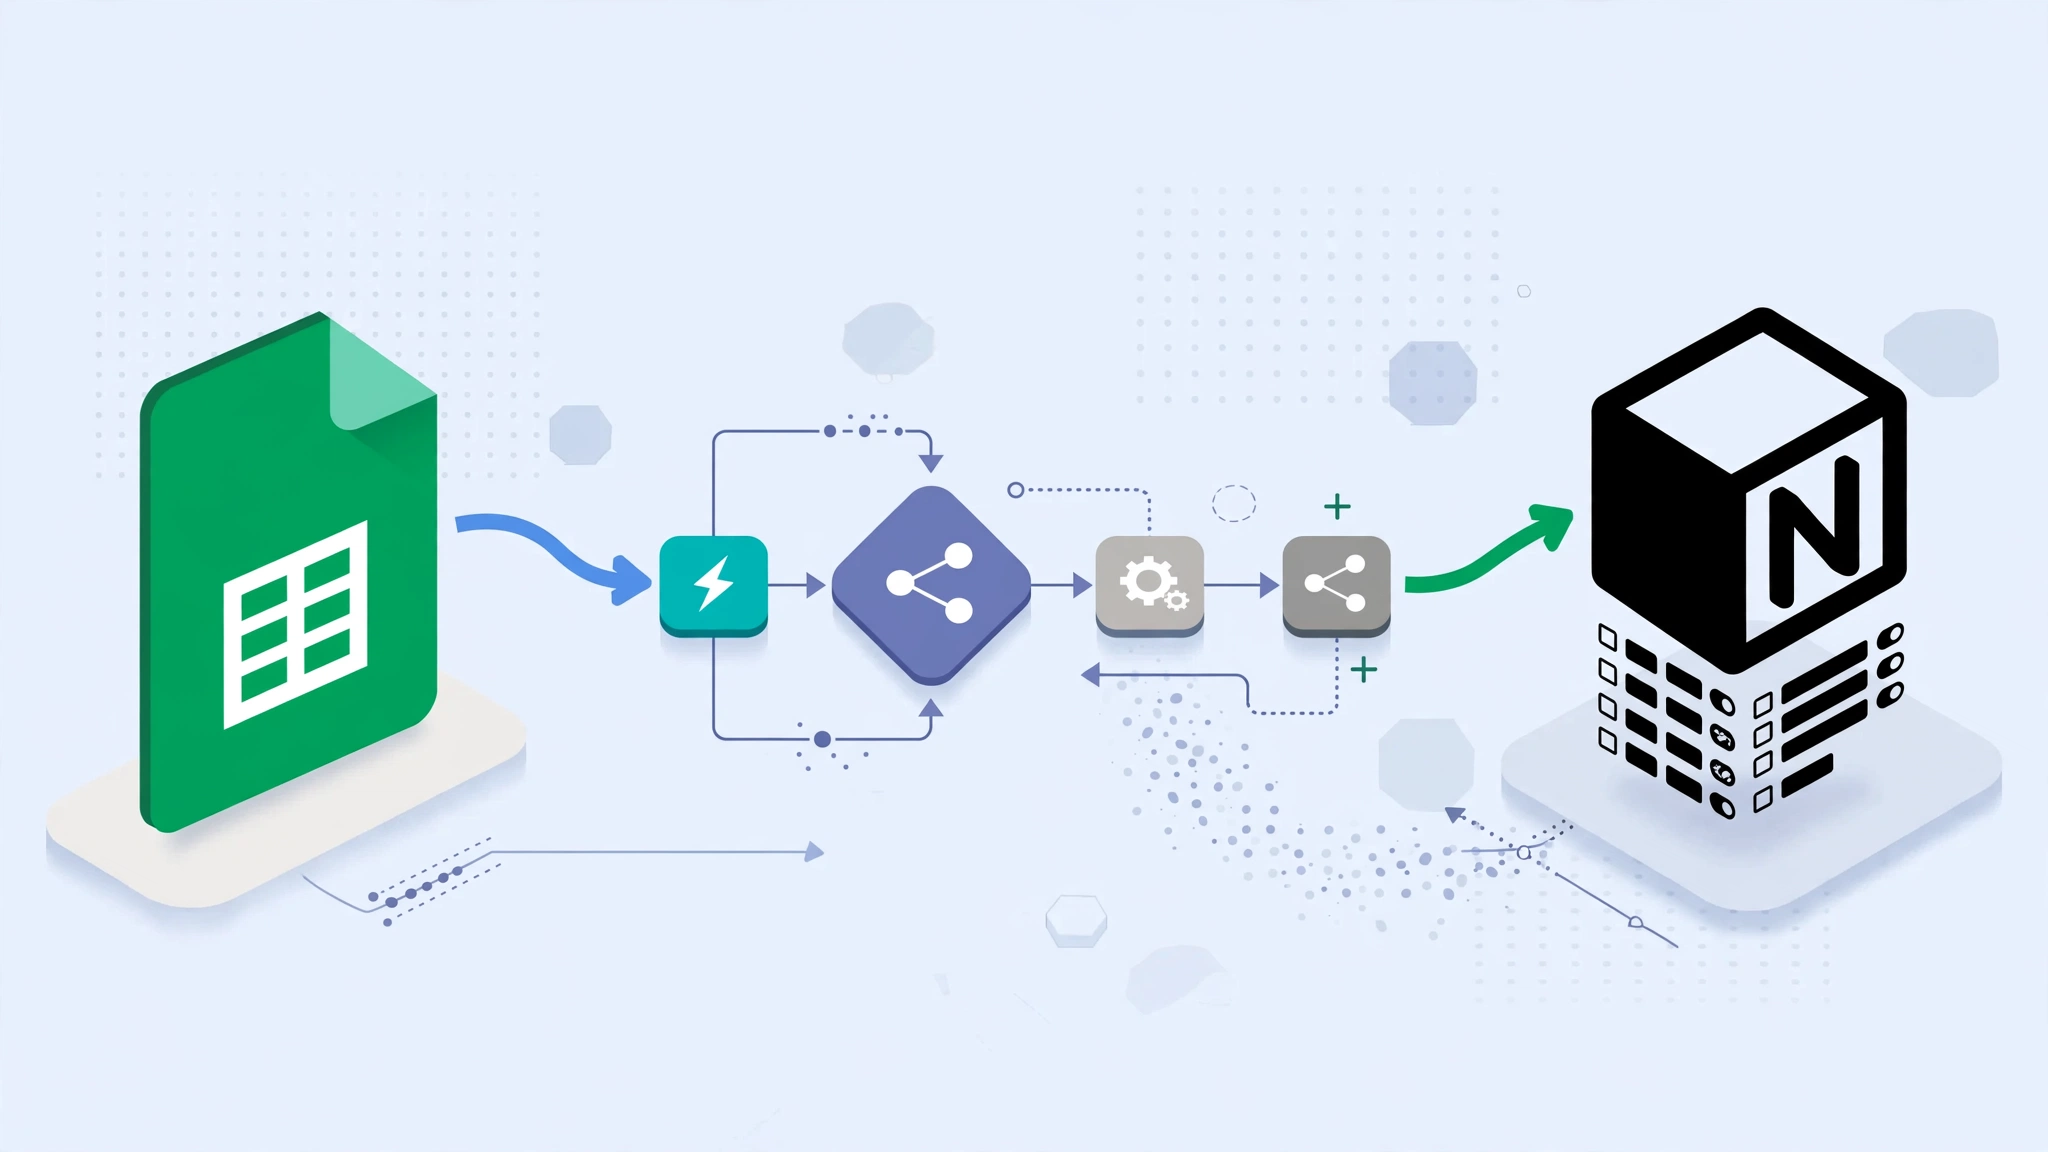
Instead of copying information manually, you can use n8n to sync Google Sheets with Notion.
This guide explains a practical one-way synchronization workflow, how to prevent duplicate Notion records, how to handle updates safely, and what to consider before attempting a more complicated two-way sync.
What Are We Building?
The basic workflow is:
Google Sheets
      ↓
n8n
      ↓
Validate and Transform
      ↓
Find Existing Notion Record
      ↓
Create or Update
      ↓
Log Result
Google Sheets remains the source of the incoming structured data, while Notion becomes the destination used for dashboards, project tracking, or team workflows.
Why Use n8n Between Google Sheets and Notion?
You could write your own script using the Google Sheets and Notion APIs.
n8n is useful because it provides a visual layer for:
authentication;
scheduled execution;
data transformation;
conditional branching;
API calls;
error handling;
execution history.
This makes the workflow easier to inspect than a collection of disconnected scripts.
It does not automatically make the workflow reliable, secure, or compliant. Those qualities still depend on how you design and operate it.
Example Use Case
For this tutorial, imagine a Google Sheet containing support tickets.
The columns are:
ID
Subject
Description
Status
Assignee
Created Date
Priority
We want each row to create or update a corresponding record in a Notion database.
The important field will be ID.
That ID acts as our stable identifier so the workflow can determine whether a row already exists in Notion.
Before You Start
You will need:
a Google account with access to the spreadsheet;
a Notion workspace;
a Notion database or data source for the synchronized records;
an n8n instance;
credentials for Google Sheets and Notion configured in n8n.
The exact authentication screens and node options can change between n8n and API releases, so use the current n8n documentation when connecting the accounts.
Step 1: Prepare the Google Sheet
Create a spreadsheet with predictable column names.
For example:
ID
Subject
Description
Status
Assignee
Created Date
Priority
TKT-001
Login problem
User cannot sign in
Open
alex@example.com
2026-09-01
High
Use a Stable ID
This is one of the most important parts of the workflow.
Do not use the row number as the permanent identity of the record.
Rows can move when someone sorts or inserts data.
Instead, create a unique ID such as:
TKT-001
TKT-002
TKT-003
That ID should not change during the lifetime of the record.
Step 2: Prepare the Notion Database
Create a Notion database with corresponding properties.
For example:
Subject — Title
ID — Text
Description — Text
Status — Select or Status
Assignee — Text or another appropriate property
Created Date — Date
Priority — Select
Last Synced — Date
The property types need to match the values the workflow sends.
For example, sending arbitrary text into a Notion date property will fail if it cannot be interpreted correctly.
Step 3: Connect Google Sheets to n8n
In n8n, create Google Sheets credentials using the authentication method supported by your environment.
Then add a Google Sheets node and select:
the Google account;
the spreadsheet;
the relevant sheet or tab;
the operation that reads rows.
Run the node once and inspect its output.
Do not continue building the workflow until the returned fields match what you expect.
Step 4: Connect Notion to n8n
Create a Notion integration and give it access only to the pages or databases required by this workflow.
Then create the Notion credential inside n8n.
A useful security rule is:
Do not give an automation access to more Notion content than it actually needs.
If the workflow only updates one support database, there is usually no reason to expose unrelated workspace content to the integration.
Step 5: Add a Trigger
For the simplest version, use a schedule.
For example:
Schedule Trigger
      ↓
Google Sheets
You might run it periodically depending on how fresh the data needs to be.
There is no universal requirement to run every minute or every five minutes.
Higher frequency creates more API traffic and more opportunities for overlapping executions.
Step 6: Read the Sheet Rows
Add the Google Sheets node after the trigger.
The output should produce one n8n item for each row you want to process.
This gives the transformation logic a predictable output.
Step 16: Handle Dates Carefully
Dates are another common source of errors.
Google Sheets can return dates differently depending on configuration and how the value is read.
Do not assume every Sheets date is automatically a Unix timestamp.
Inspect the actual value first.
Then convert it deliberately into an ISO 8601 date that Notion accepts.
Step 17: Add Error Handling
A production workflow should not simply stop without visibility when one item fails.
Common errors include:
Google authentication failure;
Notion authentication failure;
invalid property type;
missing required field;
API rate limiting;
temporary network failure;
deleted or inaccessible Notion destination.
Use n8n’s current error-handling features to route failures into a dedicated workflow or notification path.
Keep the failure information useful:
record ID;
workflow name;
failed step;
error message;
execution timestamp.
Step 18: Do Not Log Sensitive Payloads Unnecessarily
Execution logs can become a secondary copy of your business data.
If the Sheet contains:
customer information;
employee data;
private support conversations;
financial information;
review what n8n stores in execution history.
Logging everything indefinitely can create a privacy and security problem of its own.
Step 19: Respect Google Sheets API Limits
The Google Sheets API has usage quotas.
Current Google documentation recommends combining multiple reads or writes where practical because batch operations improve efficiency. :contentReference[oaicite:1]{index=1}
Do not design the workflow around outdated hard-coded quota numbers copied from old tutorials.
If Google returns a rate-limit response, apply retries with backoff rather than immediately repeating requests in a tight loop.
Step 20: Respect Notion API Rate Limits Too
Notion also applies rate limits.
Do not assume a fixed request-per-second number will remain unchanged forever.
Use the API’s returned status and retry guidance where available, and avoid making unnecessary requests.
Reduce Repeated Lookups
If every row requires:
one Notion search;
one update;
then 1,000 rows can generate a large number of API calls.
At larger scale, consider maintaining a mapping of:
Source ID → Notion Page ID
in a reliable store.
Do not cache IDs blindly forever, but there is also no reason to claim that Notion page IDs routinely change whenever pages move. The workflow should simply handle missing or inaccessible pages gracefully.
Step 21: Batch Carefully
Batching does not necessarily mean Notion provides a native “create 100 pages in one request” operation.
Instead, batching in n8n often means controlling how many items the workflow processes at a time.
For example:
1000 rows
   ↓
Process 20
   ↓
Wait / Continue
   ↓
Process Next 20
This helps control memory use and API pressure.
Step 22: Avoid Overcomplicating the First Version
The first production-worthy workflow does not need:
Redis;
multiple n8n workers;
a load balancer;
Prometheus;
Grafana;
custom CI/CD;
two-way synchronization.
Start with:
Schedule
  ↓
Read Rows
  ↓
Normalize
  ↓
Find by ID
  ↓
Create or Update
  ↓
Error Handling
Only add infrastructure when the workflow actually needs it.
Two-Way Sync Is Much Harder
It is tempting to say:
“If Sheets changes, update Notion. If Notion changes, update Sheets.”
But two-way synchronization creates several new problems.
Conflict Example
At 10:00:
Sheets Status = Open
At 10:01, someone changes Notion to:
Status = Resolved
At 10:02, someone changes Sheets to:
Status = Escalated
Which value should win?
Without explicit ownership or conflict-resolution rules, the systems can continuously overwrite each other.
A Safer Two-Way Sync Design
If two-way synchronization is genuinely necessary, define:
which system owns each property;
how changes are timestamped;
how the source of a change is recorded;
how loops are prevented;
what happens when both sides change;
how conflicts are surfaced to humans.
Example Ownership Model
Field
System of Record
ID
Google Sheets
Subject
Google Sheets
Priority
Google Sheets
Internal Notes
Notion
Review Status
Notion
This is usually easier to reason about than letting both systems edit everything.
When a Webhook Makes Sense
A schedule is often simpler.
Webhooks become useful when:
changes need to propagate quickly;
the source platform exposes a suitable event mechanism;
you can verify incoming requests;
the workflow can safely handle duplicate events.
Do not add webhook infrastructure only because “real-time” sounds better.
Security Considerations
A Sheets-to-Notion workflow may move business information between multiple systems.
Review:
who can access the Google Sheet;
which Notion pages the integration can access;
who can modify the n8n workflow;
where n8n credentials are stored;
how much execution data is retained;
whether the n8n instance is exposed to the public internet;
which fields contain personal or confidential information.
Self-Hosting Does Not Automatically Mean Secure
Self-hosting can provide more control over infrastructure and credential storage.
But it also makes you responsible for:
patching;
TLS configuration;
network security;
backups;
access controls;
monitoring;
incident response.
Do not treat self-hosting itself as proof of GDPR, HIPAA, SOC 2, or other compliance.
How to Make the Workflow Easier to Maintain
Use descriptive node names.
For example:
Read Support Tickets
Normalize Ticket Fields
Validate Ticket ID
Find Ticket in Notion
Create New Ticket
Update Existing Ticket
Record Sync Failure
This is easier to maintain than nodes named:
Google Sheets1
Code3
IF2
Notion4
Document Important Decisions
Add notes explaining:
which system owns each field;
why a field is transformed;
how duplicate detection works;
what happens when an API is unavailable;
who maintains the workflow.
A Practical Testing Checklist
Before activating the workflow, test:
a normal new row;
an existing row that needs updating;
a row without an ID;
an empty optional field;
an invalid status value;
an invalid date;
a temporarily unavailable Notion destination;
duplicate execution of the same source row.
The last test is especially important.
Running the same input twice should not create duplicate business records.
When Google Sheets Is the Wrong Source
Google Sheets works well for relatively simple collaborative datasets.
It becomes less attractive when:
the dataset is extremely large;
many systems write simultaneously;
strict transactional guarantees are required;
complex relational data is involved;
high-frequency synchronization is required.
At that point, a database may be a better system of record.
When Notion Is the Wrong Destination
Notion works well for team-visible records and knowledge workflows.
It may not be the best destination for:
high-volume telemetry;
raw event streams;
large analytical datasets;
systems requiring strict transactions;
machine-to-machine workloads with very high write rates.
Automation should fit the tools rather than forcing the tools into workloads they were not designed to handle.
How This Guide Was Prepared
This guide focuses on a practical synchronization pattern rather than a claim that there is one official architecture for connecting Google Sheets, Notion, and n8n.
The workflow uses observable concepts that remain useful even when individual node interfaces change:
a stable source identifier;
data normalization;
lookup before create;
controlled updates;
field ownership;
error handling;
human-readable execution history.
n8n nodes, Google APIs, Notion APIs, authentication methods, quotas, and property models can change over time. Verify current official documentation before deploying the workflow.
The examples here are architectural patterns. They are not claims that named companies or organizations use these exact workflows.
Frequently Asked Questions
Can n8n automatically sync Google Sheets with Notion?
Yes.
n8n can read data from Google Sheets and use it to create or update records in Notion.
The reliability of the sync depends on how you handle identifiers, duplicates, field mapping, errors, and conflicts.
Do I need to code?
Not for a basic workflow.
Many transformations can be built with n8n’s visual nodes and expressions.
JavaScript becomes useful when your mapping or validation logic becomes more complex.
Can I sync changes both ways?
Yes, but two-way sync is substantially more complicated than one-way synchronization.
You need rules for ownership, conflict resolution, update loops, and timestamps.
Start with one-way sync unless you genuinely need both directions.
How do I prevent duplicate Notion records?
Use a stable unique identifier from the source system.
Before creating a Notion record, search for that ID.
If it exists, update it. If it does not, create it.
Can I use the row number as the unique ID?
It is usually a poor choice.
Rows can change position when users sort, insert, or delete data.
A dedicated ID column is more reliable.
Should I use Google Sheets as the system of record?
It can work for smaller collaborative workflows.
For more complex, transactional, or high-volume systems, a database may be a better source of truth.
Does self-hosted n8n make the sync private?
Not automatically.
Google Sheets and Notion remain external services, so data sent to those platforms still leaves the n8n host.
Self-hosting mainly gives you more control over the orchestration layer.
Final Takeaway
A reliable Google Sheets-to-Notion workflow does not need to be complicated.
The most important pieces are:
use a stable record ID;
normalize the incoming data;
validate required fields;
search before creating;
update only the fields your source owns;
keep errors visible;
avoid unnecessary two-way synchronization.
Start with a simple one-way sync and test it against duplicate runs, bad data, and temporary API failures.
Only add webhooks, two-way updates, batching infrastructure, Redis, or distributed n8n workers when the workflow has a real need for them.
Map fields explicitly, test updates and deletions on copies, protect credentials, and add an idempotency key so retries do not create duplicate pages or rows.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. This guidance favors documented, reversible checks. Product APIs, permissions, and policies can change; verify current details before acting.
Tutorial Workflow. A repeatable path from preparation and execution to validation and recovery.
A backup is only useful if you know whether it actually ran.
Windows can copy files to another drive, a NAS, or cloud storage, but it is also useful to keep a simple record of each backup: when it ran, which files were processed, whether verification succeeded, and whether anything failed.
Google Sheets can work well as that backup log.
It should not be treated as the place where you store your actual backup files. Instead, PowerShell can perform or inspect your backup process and then send status information to a Google Sheet through the Google Sheets API.
This guide shows how to build a simple Windows 11 backup monitoring workflow with PowerShell and Google Sheets.
First: Google Sheets Is Not the Backup Destination
This distinction is important.
A real backup should create an independent copy of your important files.
That copy might live on:
an external HDD or SSD;
a NAS;
another computer;
approved cloud storage;
a dedicated backup service.
Google Sheets can then record information about that process.
Example Architecture
Important Files
      ↓
Backup Script / Backup Tool
      ↓
External Drive / NAS / Cloud Storage
      ↓
Verification
      ↓
Google Sheets Backup Log
This gives you two different things:
backup storage: where the recoverable copy exists;
backup monitoring: where status and verification information is recorded.
What Should the Google Sheet Record?
A useful backup log can contain fields such as:
timestamp;
computer name;
source path;
destination path;
file size;
SHA-256 hash where useful;
backup status;
verification status;
error message;
duration.
This makes the Sheet a lightweight monitoring dashboard instead of pretending that spreadsheet rows are the backup itself.
What You Need
A basic setup requires:
Windows 11;
PowerShell;
a Google account;
a Google Cloud project;
the Google Sheets API enabled;
a spreadsheet for backup logs;
a real backup destination.
WSL2 is not required for this workflow.
PowerShell alone is enough for file inspection, hashing, scheduled tasks, and REST API requests.
Do You Need PowerShell 7?
PowerShell 7 is a good choice for new automation projects, but it is inaccurate to say that Windows PowerShell 5.1 cannot use Invoke-RestMethod or handle JSON.
Invoke-RestMethod has existed since earlier Windows PowerShell releases and supports REST requests and JSON responses. :contentReference[oaicite:2]{index=2}
For a new script, using a current supported PowerShell release is still sensible because it receives newer fixes and features.
Step 1: Create the Google Sheet
Create a spreadsheet specifically for backup monitoring.
You can add more columns later if your workflow becomes more sophisticated.
Step 2: Create a Google Cloud Project
Open Google Cloud Console and create or select a project.
Enable:
Google Sheets API
You do not need to enable unrelated APIs simply because the workflow uses OAuth.
Step 3: Create OAuth Credentials
For a script that acts on behalf of a user, create an OAuth client appropriate for a desktop application.
Google’s current OAuth documentation supports the loopback IP flow for Windows desktop applications. A desktop application can listen on a local address such as:
http://127.0.0.1:RANDOM_PORT
The application then receives the authorization response locally. Google recommends using the system browser for this flow. :contentReference[oaicite:3]{index=3}
Do not use the old manual copy-and-paste OAuth flow. Google documents that method as deprecated and unsupported. :contentReference[oaicite:4]{index=4}
Service Account or User OAuth?
The draft version of this guide said service accounts must never be used. That is too absolute.
Both approaches can be valid.
User OAuth
This is useful when:
the Sheet belongs to a specific user;
the script should operate using that user’s authorization;
interactive authorization is acceptable during initial setup.
Service Account
This may be appropriate for controlled server-side or organizational automation where the spreadsheet is explicitly shared with the service account.
The correct choice depends on ownership, deployment architecture, and access-control requirements.
Step 4: Use the Minimum OAuth Scope
If the script only needs to read and write spreadsheet content, the Google Sheets scope is typically sufficient:
https://www.googleapis.com/auth/spreadsheets
Avoid requesting broader Google Drive or account scopes unless your workflow actually needs them.
Step 5: Create a Real Backup Before Logging Anything
For demonstration purposes, imagine we want to copy:
C:\Users\YourName\Documents\Research
to:
E:\Backups\Research
You could use an existing backup tool or a Windows utility such as Robocopy.
Do not blindly copy this command into an important production workflow.
Read the current Robocopy documentation and test against disposable files first, especially before adding options that delete or mirror destination content.
Step 6: Collect Backup Metadata With PowerShell
After the backup runs, PowerShell can collect information that will later be sent to Google Sheets.
Do not assume a scheduled task works simply because registration succeeded.
Step 12: Keep a Local Log Too
Google Sheets should not be the only place where errors are recorded.
If internet access is unavailable, the API cannot receive the failure log.
Maintain a local log such as:
C:\ProgramData\BackupMonitor\backup.log
Record information such as:
start time;
end time;
backup exit code;
verification result;
Google API result;
errors.
Step 13: Queue Google Sheets Updates When Offline
A useful improvement is to separate the backup operation from remote logging.
For example:
Backup completes
      ↓
Write event to local JSON queue
      ↓
Internet available?
   ↙             ↘
 No              Yes
 ↓                ↓
Keep queue    Send to Sheets
                  ↓
             Remove queued item
This prevents a Google API outage from causing the actual backup process to fail.
Step 14: Watch for Google Sheets API Quotas
Do not send one API request for every individual file if thousands of files are involved.
Batch or summarize where practical.
As of the current Google documentation, Sheets API quotas include:
300 read requests per minute per project;
60 read requests per minute per user per project;
300 write requests per minute per project;
60 write requests per minute per user per project.
Google also states that requests within the per-minute quota currently have no daily request limit, although its pricing documentation notes that the model may evolve. :contentReference[oaicite:8]{index=8}
Handle HTTP 429 Correctly
If quota is exceeded, Google recommends exponential backoff rather than immediately retrying in a tight loop. :contentReference[oaicite:9]{index=9}
The retry logic should also stop after a reasonable number of attempts.
Step 15: Do Not Log Every Full File Path by Default
File paths themselves can reveal sensitive information.
could reveal confidential information even though the actual document was never uploaded.
Consider logging:
a relative path;
a project identifier;
a sanitized label;
only the parent category.
Choose the minimum metadata required for monitoring.
Step 16: Be Careful With Hashes
SHA-256 hashes are useful for file-integrity comparison.
But calling hashes inherently harmless or anonymous is too broad.
A hash can still reveal useful information when an attacker already possesses candidate files and compares their hashes.
Treat hashes as operational metadata and apply appropriate access control.
Step 17: Create a Simple Dashboard
Once the log contains enough entries, Google Sheets can display useful status information.
Examples:
last successful backup;
failed backup count;
unverified files;
last run by computer;
backup duration trends.
Conditional formatting can highlight failures without adding more automation infrastructure.
Step 18: Alert Only When Something Needs Attention
Instead of notifying users after every successful run, alert on meaningful conditions.
For example:
backup failed;
destination is unavailable;
hash verification failed;
backup has not succeeded for a defined period;
Google logging has been offline for several runs.
This reduces alert fatigue.
Step 19: Separate Backup Failure From Logging Failure
These are different problems.
For example:
Backup: SUCCESS
Google Sheets Log: FAILED
does not mean your files were not backed up.
Likewise:
Backup: FAILED
Google Sheets Log: SUCCESS
means the monitoring system worked—but the backup itself did not.
Store both statuses separately.
Step 20: Test Recovery
A monitoring dashboard can tell you that files were copied and hashes matched.
It still does not prove that you can recover your data during a real failure.
Periodically restore a non-critical file from the backup destination.
Confirm that:
the file exists;
you can access it;
it opens correctly;
you understand the recovery process.
Recovery testing is more valuable than a spreadsheet filled with green “Success” rows.
A Better Overall Architecture
Windows Files
     ↓
Backup Engine
     ↓
Independent Backup Destination
     ↓
Verification
     ↓
Local Audit Log
     ↓
Queue
     ↓
Google Sheets API
     ↓
Monitoring Dashboard / Alerts
This architecture avoids making Google Sheets a dependency for the actual backup.
What Google Sheets Is Good At Here
small-scale status tracking;
human-readable logs;
simple dashboards;
collaborative monitoring;
lightweight alerting workflows;
proof that scheduled jobs are running.
What Google Sheets Is Not Good At
storing actual backup files;
massive machine telemetry;
high-frequency logging;
long-term enterprise log retention;
replacing a SIEM;
replacing dedicated backup software.
If the project grows beyond a few machines or produces large amounts of telemetry, a proper logging database or monitoring platform may become a better fit.
Security Checklist
Use a dedicated spreadsheet.
Restrict sharing.
Request only required OAuth scopes.
Protect refresh credentials.
Never store passwords or API keys in the Sheet.
Minimize file-path information.
Keep local logs protected.
Do not make backup success depend on Google Sheets availability.
Review who can access the Sheet periodically.
How This Guide Was Prepared
This guide deliberately separates backup storage from backup monitoring.
Google Sheets is used as a lightweight status and metadata ledger, while the actual backup must be written to an independent storage destination.
The implementation is based on standard Windows scripting concepts and Google’s documented Sheets API and OAuth mechanisms.
API quotas, OAuth behavior, PowerShell versions, Windows features, and Google Cloud settings can change over time. Before deploying the workflow, verify current official documentation and test it using non-critical data.
This guide also avoids presenting the workflow as automatically compliant with GDPR, HIPAA, or any other regulatory framework. Compliance depends on the data, organization, access model, agreements, jurisdiction, and complete system architecture.
Frequently Asked Questions
Can Google Sheets back up my Windows files?
Not in the architecture described here.
The actual files should be copied to external storage, a NAS, cloud storage, or another appropriate backup destination.
Google Sheets records information about that backup.
Can I log an entire folder?
Yes, but logging every individual file may create unnecessary volume.
For large folders, it may be better to record one summary row containing:
number of files;
total size;
backup result;
verification result;
duration.
Do I need PowerShell 7?
Not necessarily.
Modern PowerShell is recommended for new projects, but Windows PowerShell 5.1 already supports REST requests and JSON processing. :contentReference[oaicite:10]{index=10}
Do I need WSL2?
No.
This workflow can be built entirely with Windows and PowerShell.
Can I use a service account?
Potentially.
A service account can be appropriate for controlled automation if the spreadsheet and permission model are designed for it.
User OAuth is often simpler for a script operating directly on behalf of one user.
Is Google Sheets suitable for hundreds of computers?
It may become awkward at larger scale.
For many endpoints or high-frequency telemetry, consider a proper database, centralized logging system, or monitoring platform instead.
Does a successful SHA-256 comparison prove my backup is safe?
No.
It shows that the compared files contained identical data at the time of hashing.
You should still maintain independent copies and periodically test recovery.
Is this automatically GDPR or HIPAA compliant?
No.
No individual script, API, spreadsheet configuration, or encryption feature automatically establishes compliance.
Regulated environments require broader legal, technical, organizational, and contractual controls.
Final Takeaway
The most important improvement to this project is conceptual:
Do not use Google Sheets as your backup. Use it to monitor your backup.
Let Windows or another backup system create the recoverable copy. Then let PowerShell collect useful metadata, verify results, write a local audit trail, and send a concise status record to Google Sheets.
That gives you a transparent workflow without confusing monitoring with data protection.
Start with one folder and one backup destination. Verify that you can restore a file. Add Google Sheets monitoring afterward. Once that works reliably, automate scheduling, alerts, retries, and multi-machine reporting.
Use least-privilege credentials, never place secrets in scripts or sheets, log failures clearly, and verify that a reported backup can actually be restored.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. This guidance favors documented, reversible checks. Product APIs, permissions, and policies can change; verify current details before acting.
Tutorial Workflow. A repeatable path from preparation and execution to validation and recovery.
Ollama makes it possible to run large language models directly on a Windows PC without sending every prompt to a cloud AI service.
You can use it to experiment with models, build local AI applications, connect AI to development tools, or simply run a private chatbot on your own computer.
And on current versions of Ollama, Windows users do not need to install WSL2 just to get started. Ollama provides a native Windows installation path.
This guide explains how to install and run Ollama locally on Windows, choose an appropriate model, verify whether your GPU is being used, connect to the local API, and troubleshoot common problems.
What Is Ollama?
Ollama is a tool for downloading, running, and managing supported AI models locally.
Instead of sending each prompt to a remote API, the model runs on your computer using available CPU, memory, and supported GPU resources.
Ollama also exposes a local API, which makes it possible to connect local models to:
Python applications;
development tools;
automation workflows;
local chat interfaces;
RAG applications;
other software that can send HTTP requests.
Why Run AI Locally?
Local AI has several practical advantages.
More Control Over Data Flow
When inference runs locally, prompts can remain on the machine rather than being sent to a remote inference API.
However, local execution does not automatically make an entire workflow private.
If your application also connects to cloud storage, web search, remote APIs, telemetry services, or other external systems, those parts of the workflow may still transmit information.
No Per-Request API Charge for Local Inference
Once a model has been downloaded, local inference does not require paying a hosted model provider for each prompt.
You still pay indirectly through hardware, electricity, storage, and your own maintenance time.
Works Without Continuous Internet Access
After Ollama and the required model files are available locally, many basic inference tasks can run without an active internet connection.
Useful for Development
A local model is convenient when testing:
AI application prototypes;
prompt workflows;
local APIs;
RAG systems;
automation experiments.
What Does Your Windows PC Need?
There is no single hardware specification that guarantees a good Ollama experience.
Requirements depend heavily on:
the model;
model size;
quantization;
context length;
available RAM;
available GPU memory;
how fast you expect inference to run.
RAM Matters
Smaller models are generally easier to run on ordinary laptops.
Larger models require substantially more memory.
If you are new to local AI, start with a small model rather than downloading the largest option immediately.
Disk Space Matters Too
Model files can consume several gigabytes each.
For example, the current Ollama library lists the default Llama 3.2 model at about 2 GB, while the current Phi-4 package is about 9.1 GB. Exact sizes depend on the specific model variant.
GPU Acceleration Is Optional
Ollama can run models using CPU resources, but supported GPUs can make inference significantly more practical.
Whether a particular GPU is supported and how Ollama uses it can change as Ollama evolves, so check current official documentation rather than relying on an old CUDA version requirement.
Step 1: Install Ollama on Windows
The simplest current option is the official Windows installer.
The official page also provides a PowerShell installation command:
irm https://ollama.com/install.ps1 | iex
If you prefer not to execute an installation script directly from PowerShell, use the downloadable Windows installer from the official site instead.
Verify the Installation
Open PowerShell or Windows Terminal and run:
ollama --version
If Ollama is installed correctly, the command should return the installed version.
Step 2: Run Your First Model
The basic syntax is:
ollama run MODEL_NAME
Ollama downloads the model automatically if it is not already available locally.
Beginner-Friendly Example: Llama 3.2
Ollama’s current library provides Llama 3.2 in relatively small 1B and 3B variants, making it a practical starting point for users who do not have a high-end workstation.
Run:
ollama run llama3.2
The current default package is approximately 2 GB and uses the 3B model variant.
For an even smaller version:
ollama run llama3.2:1b
Another Option: Phi-4
Phi-4 is a substantially larger model.
Ollama currently lists Phi-4 as a 14B-class model with a package size of approximately 9.1 GB and a 16K context window.
Run:
ollama run phi4
Because Phi-4 is much larger than Llama 3.2 1B or 3B, expect it to require more memory and generally more capable hardware.
Mistral
Mistral models are also available in Ollama’s model library.
For example:
ollama run mistral
Before choosing a model, check its current Ollama library page for size and available variants.
Step 3: Chat With the Model
After running:
ollama run llama3.2
you will enter an interactive prompt.
You can type something like:
Explain the difference between RAM and storage in simple English.
The response is generated by the locally running model.
Exit the interactive session using the appropriate Ollama command or terminal shortcut shown by the current CLI.
Step 4: See Which Models Are Installed
Run:
ollama list
This displays models currently stored locally.
It is useful when your model library begins consuming significant disk space.
Step 5: Download a Model Without Starting a Chat
You can download a model separately using:
ollama pull llama3.2
This is useful when you want to prepare a machine before working offline.
Step 6: Remove a Model You No Longer Need
Local models can occupy a lot of storage.
Remove an unused model with:
ollama rm MODEL_NAME
For example:
ollama rm llama3.2
Run ollama list afterward to confirm which models remain installed.
Step 7: Check Whether Your GPU Is Being Used
GPU detection depends on your hardware and current Ollama support.
For an NVIDIA system, one useful Windows diagnostic tool is:
nvidia-smi
Run it while a model is generating output and observe whether Ollama-related processing appears and GPU memory usage changes.
If GPU acceleration does not appear to work:
update the GPU driver;
restart Ollama;
restart Windows if needed;
verify that the GPU is supported by the current Ollama release;
check current Ollama troubleshooting documentation.
Avoid installing random CUDA versions simply because an older tutorial recommends one. Current native Ollama releases may manage GPU support differently from older WSL-focused setups.
Step 8: Use Ollama’s Local API
One of Ollama’s most useful features is its local HTTP API.
The default local endpoint commonly uses:
http://localhost:11434
For example, the current Ollama model library demonstrates chat requests using the local API.
Command quoting differs between Windows shells, so adjust the syntax if you use PowerShell instead of Command Prompt.
Step 9: Use Ollama With Python
Ollama provides a Python package that can communicate with the local service.
Install it:
pip install ollama
Then create a simple example:
from ollama import chat

response = chat(
    model='llama3.2',
    messages=[
        {
            'role': 'user',
            'content': 'Explain local AI in three sentences.'
        }
    ]
)

print(response.message.content)
This gives you a simple foundation for building local AI applications without manually constructing HTTP requests.
Step 10: Use Ollama With Other Frameworks
Ollama can also be used as a local model backend for software that supports it.
Depending on the project, that may include:
LangChain;
LlamaIndex;
local chat interfaces;
development assistants;
automation platforms.
Integration packages and APIs change quickly, so use the current documentation for the framework you choose rather than copying an older package name.
Step 11: Create a Custom Model Configuration
Ollama supports a Modelfile for defining model behavior and parameters.
A simple example might look like:
FROM llama3.2

SYSTEM """
You are a concise technical assistant.
Explain concepts using simple examples.
"""

PARAMETER temperature 0.3
Then create the model:
ollama create my-assistant -f Modelfile
Run it:
ollama run my-assistant
This is useful when you want reusable instructions rather than repeatedly entering the same system prompt.
Step 12: Be Careful With Context Size
Long context windows allow models to work with more text at once, but larger contexts consume additional memory and can reduce performance.
Do not automatically set the context to the largest number supported by a model.
Increase it only when your task actually requires more context.
The maximum supported context also depends on the specific model, not just Ollama itself.
Do You Still Need WSL2?
Not for a normal Ollama installation on current Windows systems.
The native Windows installer is usually the simplest starting point.
WSL2 may still be useful if:
your development environment already runs primarily in Linux;
you need Linux-specific tooling around Ollama;
your application stack is deployed or tested inside WSL;
you specifically prefer Linux package and shell workflows.
But WSL2 should be treated as an optional development environment, not a mandatory Ollama prerequisite.
Choosing a Model for Your Hardware
The easiest approach is to start smaller and move upward.
Use Case
Suggested Starting Point
Why
Basic experimentation
Llama 3.2 1B
Small download and relatively lightweight
General local chat
Llama 3.2
Practical balance for many PCs
More demanding reasoning
Phi-4
Larger model, higher hardware requirements
Experimenting with alternatives
Mistral or another library model
Useful for comparing behavior
This is not a universal performance ranking.
Model quality and speed depend on the task, hardware, model version, quantization, and context settings.
Troubleshooting: “ollama” Is Not Recognized
If PowerShell returns an error similar to:
ollama : The term 'ollama' is not recognized...
try:
close the terminal;
open a new PowerShell or Windows Terminal session;
run ollama --version again;
verify that Ollama was installed successfully;
reinstall from the official Windows installer if necessary.
A newly installed application may not be visible to a terminal session that was already open before installation.
Troubleshooting: Model Is Very Slow
Slow inference can have several causes.
The Model May Be Too Large
Try a smaller model:
ollama run llama3.2:1b
The GPU May Not Be Used
Check GPU activity and update the relevant driver.
The Context May Be Too Large
Reduce the amount of text sent in each request or use a smaller context configuration.
Other Applications May Be Consuming Memory
Close memory-intensive software and try again.
Troubleshooting: Ollama Cannot Download a Model
Check:
internet connectivity;
available disk space;
firewall or proxy restrictions;
whether the model name is correct;
whether Ollama services are running normally.
Then retry:
ollama pull llama3.2
Privacy: Is Ollama Completely Offline?
The local model inference itself can run on your machine.
But saying an entire Ollama-based application is automatically “completely offline” would be too broad.
For example, your application may still:
download models;
connect to online search;
call other APIs;
send telemetry through another application;
retrieve cloud-hosted documents.
If privacy is important, audit the complete application and network flow—not only the language model runtime.
Security: Be Careful When Exposing the Ollama API
A local API is convenient, but do not expose it broadly to a network without understanding the security consequences.
If another device can reach your Ollama service, that device may potentially interact with the models or applications connected to it.
Before changing host bindings or exposing ports:
understand which interface Ollama is listening on;
use firewall controls;
avoid unnecessary public exposure;
place authentication or a controlled application layer in front of it where appropriate.
A Simple Beginner Setup
If you just want to experiment with local AI, you do not need a complex stack.
Install Ollama for Windows.
Open PowerShell.
Run ollama run llama3.2.
Ask a few questions.
Check ollama list.
Try the local API when you are ready to build an application.
Only introduce WSL, Docker, LangChain, RAG, or other infrastructure when your project actually requires them.
How This Guide Was Prepared
This guide focuses on the current native Windows installation path and Ollama commands that are documented through Ollama’s official website and model library.
Model availability, package sizes, GPU support, installation methods, context limits, CLI options, and integrations can change as Ollama and individual models are updated.
For that reason, hardware-specific claims and performance numbers in this guide are intentionally presented conservatively rather than as universal benchmarks.
Before troubleshooting a version-specific problem, check the current Ollama documentation, model library, and release information.
Frequently Asked Questions
Can Ollama run directly on Windows?
Yes.
Ollama currently provides a native Windows installer, so WSL2 is not required for a normal installation.
Does Ollama require a GPU?
No.
Models can run using CPU resources, although supported GPU acceleration can substantially improve the experience for many models.
Which model should a beginner try first?
A smaller model is usually the easiest starting point.
For example, Llama 3.2 is currently available in 1B and 3B variants through Ollama.
How much RAM does Ollama need?
There is no universal answer.
Memory requirements depend on the model, quantization, context length, and whether parts of the workload use GPU memory.
If a model is too large for your system, try a smaller variant.
Can Ollama work without internet?
Yes, for local inference after the required software and model files have already been downloaded.
Features that depend on external APIs or online resources still require connectivity.
Can I use Ollama for private company documents?
Running inference locally can reduce exposure to remote inference providers, but privacy depends on the entire system.
Before processing confidential information, check where documents are stored, what integrations are active, what logs are retained, and whether any other component sends information externally.
Running local AI on Windows with Ollama is now much simpler than many older tutorials suggest.
For most users, the process is:
install the native Windows version;
choose a model appropriate for your hardware;
run it with ollama run;
verify performance;
use the local API when you want to build applications.
You do not need to begin with WSL2, manual CUDA installation, custom quantization, or a complicated Python stack.
Start simple. Confirm that Ollama works. Learn how model size affects your computer. Then add more advanced integrations only when they solve a real problem.
Check disk space and memory first, download from the official source, test a small model, and avoid assuming local execution automatically removes every privacy or security risk.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. This guidance favors documented, reversible checks. Product APIs, permissions, and policies can change; verify current details before acting.
Tutorial Workflow. A repeatable path from preparation and execution to validation and recovery.
Research often involves repetitive work that does not require constant human judgment: checking new papers, cleaning metadata, monitoring APIs, moving information between tools, preparing summaries, and notifying collaborators.
Those are good candidates for automation.
n8n research automation can connect research databases, APIs, spreadsheets, reference managers, cloud storage, messaging tools, and AI services into repeatable workflows without requiring every step to be written as a custom script.
This guide explores practical n8n workflow ideas for literature discovery, metadata enrichment, research monitoring, data validation, collaboration, and reporting—while keeping human review in the parts of research that require interpretation and judgment.
What n8n Can Automate in a Research Workflow
n8n works best as an orchestration layer.
It can receive data from one source, transform it, send it somewhere else, apply rules, call APIs, wait for events, and notify people when something requires attention.
In research, that makes it useful for tasks such as:
monitoring literature databases;
collecting metadata;
deduplicating records;
tracking new preprints;
updating spreadsheets or databases;
validating incoming datasets;
sending weekly research digests;
archiving workflow outputs;
routing items for human review.
Automation should reduce repetitive handling—not replace researchers’ responsibility for evidence quality, interpretation, methodology, or publication decisions.
Before You Automate: Separate Mechanical Work From Research Judgment
A useful way to design research automation is to divide tasks into two categories.
Good Automation Candidates
fetching new records;
normalizing metadata;
checking identifiers;
format conversion;
scheduled monitoring;
notifications;
basic validation rules;
copying data between approved systems.
Tasks That Should Usually Remain Human-Led
deciding whether a paper is methodologically strong;
interpreting conflicting evidence;
making causal claims;
assessing research ethics;
deciding study inclusion or exclusion in formal reviews;
drawing final conclusions;
approving publication-ready research outputs.
This boundary keeps automation useful without turning convenience into false confidence.
1. Literature Monitoring From PubMed
A simple starting workflow is a scheduled PubMed search.
A weekly digest is one of the most practical research automations because it turns a large collection of incoming records into a manageable review habit.
Workflow Example
Weekly Schedule
    ↓
Fetch This Week's New Records
    ↓
Filter / Rank
    ↓
Group by Topic
    ↓
Format Digest
    ↓
Send Email or Slack Message
A digest can include:
paper title;
source;
publication date;
abstract excerpt;
priority label;
link to original source;
review status.
If AI-generated summaries are included, keep the original abstract and source URL available for verification.
10. Dataset Freshness Monitor
Research projects often depend on external datasets that change without warning.
n8n can periodically check whether a dataset or endpoint has changed.
Possible Signals
ETag;
Last-Modified header;
content hash;
version number;
release metadata.
Workflow Example
Schedule
   ↓
HEAD / GET Request
   ↓
Compare Stored Metadata
   ↓
Changed?
 ↙       ↘
Yes       No
 ↓
Download
 ↓
Validate
 ↓
Archive
 ↓
Notify Team
11. Basic Dataset Schema Validation
Before a newly downloaded dataset enters analysis, n8n can perform basic structural checks.
Examples include:
required columns exist;
file is not empty;
expected data types are present;
known identifiers are unique;
date fields parse correctly;
unexpected columns are flagged.
Complex statistical validation may be better handled by Python, R, or a dedicated data-validation tool, with n8n orchestrating the process.
12. Survey Intake and De-Identification
n8n can also help route survey responses into a controlled processing pipeline.
Possible Workflow
Form Submission
    ↓
Check Required Consent Field
    ↓
Separate Identifiers
    ↓
Apply Approved Transformation
    ↓
Store Research Record
    ↓
Notify Research Team
However, removing names alone does not guarantee anonymity.
Research involving human participants should follow the approved study protocol, institutional requirements, and applicable privacy rules.
Do not assume that an automation workflow is compliant simply because it uses hashing or redaction.
13. Research Data Quality Alerts
Instead of manually checking incoming data every day, create rules that surface suspicious records.
For example:
missing required values;
duplicate identifiers;
unexpected date ranges;
values outside plausible limits;
schema changes;
failed API responses.
The workflow can route flagged records into Slack, email, Notion, Jira, or another review system.
14. AI-Assisted Literature Matrix
A literature matrix helps researchers compare papers using consistent fields.
n8n can automate the first-pass extraction.
Example Fields
research question;
study design;
population;
sample size;
main outcome;
stated limitation;
funding information;
source citation.
If AI is used to extract these fields, retain the source text and require human confirmation for anything important.
AI extraction should accelerate review—not silently become the authoritative dataset.
15. Human-Reviewed Research Summary Draft
Research summaries are another useful automation target when the distinction between drafting and validation is clear.
Safer Workflow
Verified Research Records
    ↓
AI Draft Generation
    ↓
Attach Source References
    ↓
Human Review Queue
    ↓
Edit / Approve
    ↓
Publish or Share
The workflow should not invent citations, fill missing evidence, or convert uncertain findings into definitive conclusions.
Where possible, require the model to work only from source material supplied to it.
16. Research Collaboration Notifications
Many useful automations are simple.
For example, when a team member changes a paper’s status from:
To Review → Included
n8n could:
notify the project channel;
add the paper to a shared literature matrix;
create a reviewer task;
record the change date.
This reduces coordination overhead without interfering with research judgment.
17. Workflow Version Backups
Automation itself becomes part of the research process.
If a workflow changes, the results may change too.
That makes versioning important.
A practical setup can periodically export important n8n workflows and store them in a version-controlled repository or another protected archive.
Record Alongside the Workflow
workflow version;
date changed;
reason for change;
API versions where relevant;
expected inputs and outputs;
maintainer.
18. Research Artifact Packaging
n8n can coordinate the steps required to prepare a research artifact for archiving.
For example:
collect approved files;
collect workflow exports;
generate a manifest;
package files;
upload them to an approved repository;
record the resulting identifier or archive URL.
Repositories such as Zenodo expose APIs that can be incorporated into automated publishing workflows.
Before automatically publishing research artifacts, keep a human approval step.
19. Provenance Logging
A research workflow should make it possible to understand where a record came from and what transformations were applied.
Useful Provenance Fields
source URL;
source identifier;
retrieval timestamp;
workflow version;
processing status;
validation status;
human reviewer where applicable.
This is often more useful than attempting to save every possible internal execution detail indefinitely.
20. Error Handling and Failure Notifications
Research automation should fail visibly.
A silent failure can create missing data that researchers may not notice until much later.
Plan for Common Failures
API rate limit;
expired credentials;
network timeout;
schema changes;
malformed JSON;
missing fields;
storage failure.
Depending on the workflow, you may use retries, Wait nodes, conditional branches, error workflows, or alerts.
Always verify current n8n behavior against the official documentation because node options and error-handling features can change.
A Practical n8n Research Automation Architecture
A maintainable research pipeline usually has several distinct stages:
Keeping these stages separate makes troubleshooting and auditing easier.
Start With One Workflow, Not an Entire Research Platform
The easiest mistake is trying to automate everything at once.
Start with one repetitive problem.
For example:
“I manually check PubMed every morning.”
“I keep copying new references into a spreadsheet.”
“Our team forgets to check new preprints.”
“We spend time fixing incomplete DOI metadata.”
Automate that first.
Once it works reliably, add another stage.
Security and Privacy Considerations
Research automation can process sensitive information, so security should be designed alongside functionality.
Consider:
where n8n is hosted;
who has access to credentials;
which data is stored in execution history;
how backups are protected;
which third-party APIs receive research data;
whether sensitive inputs are included in logs;
how long execution data is retained.
Self-hosting can provide more control, but it does not automatically make a workflow compliant or secure.
Do Not Treat Automation as Research Validation
This distinction deserves emphasis.
A workflow can verify that:
a DOI resolves;
a field exists;
a date is valid;
a record is duplicated;
an API request succeeded.
It cannot automatically establish that:
a study is methodologically strong;
a conclusion is justified;
a dataset is ethically appropriate;
a paper should be included in a systematic review;
a scientific claim is true.
Those are research judgments.
How This Guide Was Prepared
This guide focuses on workflow patterns that can realistically be implemented with n8n’s general automation capabilities, APIs, webhooks, scheduling, conditional logic, and integrations.
The examples are architectural patterns rather than claims that specific universities, research institutions, government agencies, or laboratories currently use these exact workflows.
API endpoints, authentication requirements, node availability, rate limits, and n8n features change over time. Always check current documentation before implementing a workflow.
For workflows involving human subjects, regulated information, sensitive research data, or formal publication pipelines, automation should be reviewed against the relevant institutional, ethical, legal, and security requirements.
Frequently Asked Questions
Is n8n good for research automation?
It can be a good fit when research work involves repeatable data movement, API calls, notifications, metadata handling, or integration between several tools.
It is less appropriate as a replacement for statistical analysis, methodological judgment, or scientific interpretation.
Do researchers need to know how to code?
Not necessarily for simple workflows.
n8n provides a visual workflow editor and many prebuilt integrations.
More advanced workflows may still benefit from knowledge of APIs, JSON, JavaScript, authentication, databases, Docker, or infrastructure.
Can n8n work with PubMed?
Yes, PubMed data can be accessed through NCBI’s supported APIs using HTTP requests.
Use the current NCBI documentation for endpoint details and usage requirements.
Can n8n work with Zotero?
Yes, Zotero exposes a web API that can be called from n8n.
Read and write capabilities depend on authentication and the API operation being used.
Can n8n be used for systematic reviews?
It can automate supporting tasks such as literature ingestion, deduplication, metadata collection, status tracking, notifications, and drafting assistance.
Formal inclusion decisions, risk-of-bias judgments, interpretation, and final synthesis should remain under appropriate human review.
Does self-hosting n8n make research data compliant?
No.
Self-hosting gives you more control over infrastructure and data flows, but compliance depends on the complete system, including permissions, security, retention, backups, third-party services, procedures, and applicable requirements.
Can AI be added to n8n research workflows?
Yes.
AI can help classify, summarize, extract structured fields, or draft material.
Keep the original sources available and use human review when AI output could influence research conclusions.
Final Takeaway
Research automation works best when it removes repetitive handling without removing human judgment.
n8n can help researchers build workflows that:
monitor literature;
collect metadata;
verify identifiers;
deduplicate records;
track dataset changes;
route work to collaborators;
prepare weekly digests;
maintain provenance;
archive research artifacts.
Start with one repetitive task, make the workflow observable, preserve source information, route uncertainty to humans, and only scale after the first automation is reliable.
Define an owner and rollback path for every workflow, test rate limits and duplicate events, and retain source URLs and timestamps so results remain auditable.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. This guidance favors documented, reversible checks. Product APIs, permissions, and policies can change; verify current details before acting.
AI Decision Loop. Define the task, test real examples, verify evidence, and improve the workflow.
AI can summarize documents, generate ideas, analyze patterns, automate repetitive work, and help people make faster decisions.
But faster does not always mean better.
Some tasks involve values, accountability, relationships, uncertainty, or consequences that cannot safely be reduced to pattern recognition alone. In these situations, AI may still be useful as an assistant—but it should not become the final decision-maker.
This guide explains when you should not rely on AI alone and highlights seven areas where meaningful human judgment should remain central.
The Core Principle: Assistance Is Different From Authority
The important question is not:
“Can AI do this task?”
A better question is:
“Should AI have authority over the final decision?”
An AI system may be capable of:
summarizing evidence;
identifying patterns;
generating options;
predicting likely outcomes;
drafting recommendations.
But those abilities do not automatically make it appropriate to decide what should happen.
As the stakes increase, human accountability becomes more important.
1. Moral and Ethical Decisions
AI can describe ethical frameworks, compare arguments, and identify competing values.
What it cannot do is become morally responsible for the consequences of a decision.
Why This Matters
Ethical decisions often involve conflicts between legitimate values.
For example:
privacy versus public safety;
individual autonomy versus collective benefit;
fairness versus efficiency;
transparency versus confidentiality;
short-term benefit versus long-term harm.
There may be no mathematically correct answer.
People must decide which values deserve priority and accept responsibility for that choice.
AI Can Help With Ethical Deliberation
AI can still be useful for:
summarizing relevant ethical frameworks;
identifying stakeholders;
surfacing potential unintended consequences;
generating questions for discussion;
comparing different interpretations.
But the final moral judgment should remain with accountable humans.
2. High-Stakes Legal Interpretation
AI can search legal documents, summarize cases, organize evidence, and help draft documents.
But legal interpretation often requires more than retrieving relevant text.
It may involve:
jurisdiction;
binding versus persuasive authority;
procedural rules;
recent legal developments;
conflicting precedent;
strategic considerations;
professional responsibility.
Why AI Alone Is Risky
AI systems can generate incorrect citations, misstate holdings, overlook jurisdictional differences, or present an uncertain interpretation with excessive confidence.
Even when the underlying legal text is correct, applying it to a specific situation may require professional judgment.
A Better Role for AI
AI may assist with:
case-law research;
document summarization;
issue spotting;
draft organization;
comparison of arguments.
Final legal advice, litigation strategy, judicial decisions, or other consequential legal conclusions should remain under qualified human review.
3. Clinical Diagnosis and Patient Care
AI can be valuable in healthcare.
It can help analyze images, organize patient information, summarize records, identify patterns, and support clinical workflows.
But medical care involves more than pattern recognition.
Patients Are More Than Data Points
A clinician may need to consider:
symptoms;
medical history;
medications;
physical examination;
family context;
patient preferences;
quality-of-life priorities;
uncertainty that cannot be resolved immediately.
Some of this information may never appear in structured data.
AI Can Support, But Should Not Replace, Clinical Judgment
Appropriate uses may include:
summarizing medical literature;
organizing patient records;
highlighting possible differential diagnoses;
assisting with administrative tasks;
supporting narrow validated diagnostic workflows.
But diagnosis, treatment decisions, informed consent, and other high-impact clinical decisions should involve qualified healthcare professionals.
4. Crisis Intervention
Crisis situations require a particularly high level of caution.
Examples include:
suicidal thoughts;
immediate risk of self-harm;
domestic violence;
acute psychiatric crisis;
medical emergency;
threats of violence.
Why Human Judgment Matters
Crisis response may require a person to:
recognize rapidly changing risk;
ask follow-up questions;
interpret incomplete information;
understand local emergency resources;
make decisions about escalation;
remain accountable for those decisions.
An AI system can provide general supportive information, but it should not be treated as an autonomous replacement for emergency services, qualified clinicians, crisis professionals, or trusted human support.
AI Should Know When to Escalate
In well-designed systems, one of AI’s most important functions may be recognizing when the situation exceeds its appropriate role.
A responsible system should help route a person toward appropriate human support instead of pretending that conversational fluency is equivalent to crisis expertise.
5. Leadership and High-Impact People Decisions
AI can help leaders analyze information, model scenarios, summarize employee feedback, and prepare communication.
But leadership involves responsibility for people—not only optimization.
Some Decisions Require Human Accountability
Examples include:
layoffs;
promotion decisions;
disciplinary actions;
conflict resolution;
organizational restructuring;
culture-changing decisions.
These decisions affect livelihoods, careers, relationships, and trust.
A statistical recommendation may provide useful information, but it should not replace contextual understanding or accountable leadership.
AI Can Inform Leadership Without Becoming the Leader
Useful applications include:
scenario analysis;
meeting summaries;
draft communication;
trend analysis;
identifying questions leaders should investigate.
But human leaders should remain responsible for interpreting that information and deciding what the organization will stand for.
6. Creative Authorship and Personal Expression
This category requires a little nuance.
AI absolutely can help people create.
It can:
brainstorm ideas;
generate drafts;
suggest visual concepts;
help overcome creative blocks;
explore variations;
assist with editing.
But creative assistance is different from human authorship.
Why Human Direction Still Matters
Meaningful creative work often reflects:
personal experience;
cultural context;
memory;
intent;
taste;
values;
deliberate stylistic choices.
AI can generate material that resembles these qualities, but the human creator remains responsible for deciding what the work means, what should remain, and what should be removed.
Copyright and Attribution Add Another Layer
AI-generated content also creates questions about authorship, licensing, attribution, training data, and copyright.
Those rules continue to evolve across jurisdictions.
If AI materially contributes to published creative work, creators should understand the applicable platform rules, licensing terms, and current legal guidance.
7. Diplomacy, Mediation, and Deep Human Negotiation
Negotiation is not simply an optimization problem.
People may care about:
status;
historical grievances;
trust;
symbolism;
cultural expectations;
relationships;
future cooperation.
Some agreements depend on language that is intentionally flexible or sensitive to context.
Where AI Can Help
AI may assist negotiators by:
summarizing positions;
translating documents;
comparing proposals;
mapping areas of agreement;
identifying unresolved issues;
preparing background research.
Where Human Judgment Remains Essential
Final negotiation may require interpreting:
tone;
trust;
intent;
relationship history;
cultural meaning;
political consequences.
Those judgments should remain with people who understand the parties and can be held responsible for the outcome.
A Better Framework: Ask What AI Should Be Allowed to Do
Instead of deciding whether AI should be completely used or completely banned, divide the task into levels.
Level
AI Role
Human Role
1. Inform
Retrieve and summarize information
Review the information
2. Recommend
Generate possible options
Choose among them
3. Prepare
Draft an action
Approve or reject it
4. Execute
Perform an approved action
Monitor and remain accountable
5. Decide
Make the final consequential judgment
Minimal involvement
For high-stakes human-centered tasks, the safest boundary is often to keep AI in Levels 1–3 rather than giving it final decision authority.
Three Questions to Ask Before Delegating a Decision to AI
Before allowing AI to make or execute an important decision, ask:
1. Can the Decision Be Reversed?
Generating a bad draft can be corrected.
Denying medical treatment, terminating an employee, or making a legal filing may be much harder to reverse.
2. Who Is Accountable If the AI Is Wrong?
If nobody can clearly answer this question, the system probably has too much autonomy.
3. Does the Decision Require Values or Context That Cannot Be Fully Encoded?
If the answer depends on fairness, dignity, trust, culture, consent, or other contested human values, human judgment should remain central.
Warning Signs That You Are Delegating Too Much to AI
Employees are told to follow the AI recommendation unless they can prove it is wrong.
No human can explain why a consequential decision was made.
AI output is treated as objective simply because it contains numbers.
Users cannot appeal an AI-assisted decision.
The system operates outside its original intended context.
Human reviewers become rubber stamps rather than genuine decision-makers.
People affected by the decision do not know AI was involved.
These are governance problems, not merely model-quality problems.
When AI Is Still Extremely Useful
Keeping humans responsible does not mean rejecting AI.
AI is particularly useful when it:
reduces repetitive administrative work;
organizes large amounts of information;
helps people consider alternatives;
drafts material for human review;
finds patterns that deserve further investigation;
helps experts work faster without removing their authority.
The strongest systems often combine machine scale with human accountability.
A Human-Judgment Checklist
Before using AI for an important decision, ask:
What happens if this decision is wrong?
Can the outcome be reversed?
Does the task involve health, rights, safety, employment, money, or legal consequences?
Does the decision require empathy, cultural context, or moral judgment?
Is an appropriately qualified person reviewing the result?
Can that person disagree with the AI?
Is there an appeal or escalation path?
Can we explain how the final decision was reached?
Is AI being used because it genuinely helps—or simply because automation is available?
How This Guide Was Prepared
This guide distinguishes between tasks where AI can provide useful assistance and tasks where final authority should remain with accountable humans.
The recommendations focus on consequence, reversibility, accountability, human values, professional expertise, and the difference between generating information and making consequential decisions.
AI capabilities, laws, professional standards, and organizational policies continue to evolve. Specific medical, legal, employment, security, or regulatory uses should therefore be evaluated against current authoritative guidance for the relevant jurisdiction and profession.
Frequently Asked Questions
Should AI never be used for ethical decisions?
AI can help organize arguments, identify stakeholders, and explore possible consequences.
It should not be treated as the morally accountable authority responsible for the final decision.
Can AI be used in medicine?
Yes.
AI already has useful applications in healthcare, including narrow diagnostic tasks, information processing, documentation, and workflow support.
The important distinction is between assisting qualified professionals and replacing accountable clinical judgment in consequential decisions.
Can AI be used for legal work?
Yes.
AI can assist with research, summarization, drafting, document review, and information retrieval.
But lawyers and other qualified professionals remain responsible for verifying legal authorities, complying with professional obligations, and making consequential legal judgments.
Does AI lack creativity?
AI can generate novel-looking text, images, audio, and other creative material.
The more useful distinction is that AI does not have a human biography, personal intentions, lived experience, or cultural stake in the work it generates.
Human creative direction therefore remains important when meaning, authorship, attribution, or personal expression matters.
Can AI replace managers or leaders?
AI can automate parts of management and help leaders analyze information.
But decisions affecting people, culture, trust, accountability, and organizational values should not be delegated entirely to an AI system.
What is the easiest rule for deciding whether AI should make a decision?
Ask:
If this goes wrong, would a responsible human need to explain, defend, or repair the outcome?
If the answer is yes, that human should probably remain meaningfully involved before the decision is finalized.
Final Takeaway
The question is not whether AI is powerful enough to participate in important work.
It already can.
The harder question is where its authority should stop.
AI is excellent at scale, speed, information processing, and generating options.
Humans remain essential when decisions require:
accountability;
ethical judgment;
professional responsibility;
empathy;
cultural context;
relationship awareness;
acceptance of consequences.
The most responsible future is therefore not “human versus AI.”
It is choosing carefully which parts of a task should be automated—and making sure the person responsible for the outcome never disappears from the process.
Practical example: deciding when a task should stay human-led
Take a hiring, medical, financial, or safety-related decision and map the consequences of an incorrect answer. If the cost of a mistake is high or the evidence is incomplete, AI can help organize information but should not make the final call.
Describe the decision and who is accountable for it.
Separate factual lookup from judgment, empathy, or policy interpretation.
Use AI only for the low-risk preparation step.
Require a qualified human to check evidence and approve the outcome.
Record the reason for the final decision and any uncertainty.
This boundary makes AI useful without disguising a consequential judgment as an automated answer.
Practical verification and limits
Use AI to organize or draft, but retain human responsibility for safety, legal, medical, financial, employment, and rights-affecting decisions.
Editorial review and limitations
Reviewed by Femica Maydinda Harend. This guidance favors reproducible checks and transparent uncertainty. Tools and policies change, so verify current details before acting.
AI answers can be useful, incomplete, or wrong in different ways. Review effort should match what could happen if an error is missed. This framework helps a team organize evaluation; it does not supply a universal score, benchmark, or certification.
Tier 1: Low-impact drafts
Examples include brainstorming titles or reorganizing non-sensitive notes. Review for relevance, tone, and unsupported factual additions. Keep a person responsible for the final output.
Tier 2: Work that affects a decision or external communication
Check factual claims against original sources, inspect citations, confirm required context, and review for privacy or bias concerns. Document who approves the final action.
Tier 3: High-impact or irreversible uses
Do not rely on a general-purpose answer as the decision-maker. Require qualified human review, representative evaluation data, documented access controls, an escalation route, and an incident response plan. Follow applicable laws and organizational policy.
Build a task-specific rubric
Define the user, intended purpose, and prohibited use.
List normal, ambiguous, and adversarial examples.
Set criteria for correctness, completeness, source support, refusal, privacy, and escalation.
Assign reviewers and describe what evidence they should inspect.
Reassess when a model, prompt, data source, or connected tool changes.
Separate dimensions instead of hiding them in one score
Accuracy, usefulness, fairness, privacy, latency, and cost are different questions. A high average on an easy set can conceal a dangerous failure on a rare case. Report individual failure modes and the limits of the evaluation set.
Turn the risk tier into a review decision
A useful evaluation record connects a task to an action someone can take. Record the intended user, allowed input, expected output, consequence of an error, reviewer, evidence to inspect, and what happens when the answer is uncertain. Keep these as separate fields; a single average score can hide a failure that matters.
Define the decision. State whether the model is drafting, retrieving, recommending, or changing something. Name the human who remains accountable.
Write representative cases. Include an ordinary request, missing context, conflicting evidence, an out-of-scope request, and a privacy-sensitive input that should be refused or redirected.
Set a pass condition per case. For example, a source-finding task must link to the relevant record and distinguish a quotation from an inference. Do not count fluent wording as evidence.
Route failures. Decide whether the system may retry, must ask for context, or must stop for human review. An unsafe answer should not become acceptable because the other examples passed.
Re-evaluate changes. Repeat the same cases when a model, prompt, connected tool, or source collection changes, and note what changed.
Illustrative review record
Suppose a fictional assistant summarizes a sample policy and states that “requests must be filed by 12 May.” The fictional source says “13 May.” Mark the claim contradicted, retain the source passage, correct the draft, and investigate whether the error affects other dates. This is a made-up teaching example, not a model test or a reported result.